NEWScrapingAnt MCP for Claude Code, Cursor & Windsurf — try it free →
Skip to main content

18 posts tagged with "puppeteer"

View All Tags

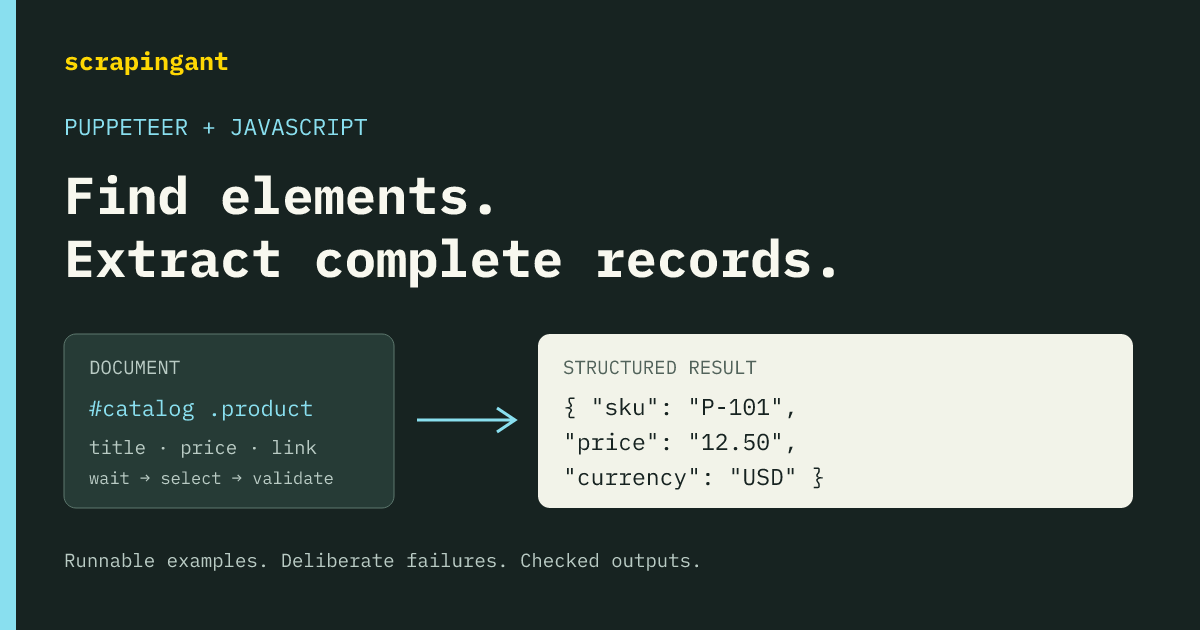
Puppeteer Find Elements: Select, Wait and Extract Records

· 14 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Puppeteer Find Elements: Select, Wait and Extract Records

Use page.$() to get the first matching element and page.$$() to get all matching elements. When you want data rather than handles, page.$eval() runs a callback on the first match, and page.$$eval() passes all matches to a callback that can return JSON records.

The selector still needs to identify the right records, and the fields must be populated before you read them. This guide demonstrates both problems with a local catalogue: a promotional card that matches an overly broad selector, and product cards that exist before their titles and prices arrive.

How to scrape a dynamic website with Puppeteer-Sharp

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

How to scrape a dynamic website with Puppeteer-Sharp

Scraping dynamic websites with Puppeteer-Sharp can be challenging for many developers. Puppeteer-Sharp, a .NET port of the Puppeteer library, enables effective browser automation in C#.

This article provides step-by-step guidance on using Puppeteer-Sharp to simplify data extraction from complex web pages. Enhance your web scraping skills now.

Proxy Rotation Implementation in Puppeteer

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Proxy Rotation Implementation in Puppeteer

This comprehensive guide explores the intricate world of proxy rotation in Puppeteer, a powerful Node.js library for browser automation. As websites increasingly implement sophisticated anti-bot measures, the need for advanced proxy rotation techniques has become paramount for successful web scraping projects (ScrapingAnt).

Proxy rotation serves as a crucial mechanism for distributing requests across multiple IP addresses, thereby reducing the risk of detection and IP blocking. Through the integration of tools like proxy-chain and puppeteer-extra, developers can implement robust proxy rotation systems that enhance the reliability and effectiveness of their web scraping operations. This guide delves into various implementation methods, from basic setup to advanced techniques, providing developers with the knowledge needed to build sophisticated proxy rotation systems that can handle complex scraping scenarios while maintaining anonymity and avoiding detection.

Bypassing CAPTCHA with Puppeteer

· 8 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Bypassing CAPTCHA with Puppeteer

As of October 2024, the use of Puppeteer, a powerful Node.js library for controlling headless Chrome or Chromium browsers, has emerged as a popular tool for automating web interactions. However, CAPTCHAs (Completely Automated Public Turing test to tell Computers and Humans Apart) continue to pose significant obstacles to seamless automation. This research report delves into the cutting-edge strategies and techniques for bypassing CAPTCHAs using Puppeteer, exploring a range of sophisticated approaches that leverage advanced technologies and methodologies.

The importance of CAPTCHA bypass techniques has grown in parallel with the increasing sophistication of CAPTCHA systems. While CAPTCHAs serve a crucial role in preventing malicious bot activities, they also present challenges for legitimate automated processes, including web scraping, testing, and data collection. Recent studies have shown remarkable progress in this field, with some techniques achieving success rates as high as 94.7% in solving image-based CAPTCHAs.

This report will examine various strategies, including advanced image recognition techniques, audio CAPTCHA solving methods, browser fingerprinting evasion, machine learning-based prediction, and distributed solving networks. Each of these approaches offers unique advantages and has demonstrated significant potential in overcoming modern CAPTCHA systems.

As we explore these techniques, it's important to note the ethical considerations and potential legal implications of CAPTCHA bypassing. While this research focuses on the technical aspects and capabilities of these methods, their application should always be considered within appropriate and lawful contexts. The ongoing cat-and-mouse game between CAPTCHA developers and bypass techniques continues to drive innovation on both sides, shaping the future of web security and automation.

Looking for CAPTCHA bypassing guide for Playwright? We got you covered!

Changing User Agent in Puppeteer for Effective Web Scraping

· 16 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Changing User Agent in Puppeteer for Effective Web Scraping

Web scraping, a technique used to extract data from websites, has become an integral part of many businesses and research endeavors. However, as websites become more sophisticated in their defense against automated data collection, scrapers must adapt and employ advanced techniques to remain undetected and ensure the continuity of their operations. User Agent manipulation stands at the forefront of these techniques, serving as a crucial element in mimicking human-like behavior and avoiding detection.

According to a study by Imperva, a staggering 37.2% of all internet traffic in 2024 was attributed to bots, with 24.1% classified as "bad bots" used for scraping and other potentially malicious activities. This statistic underscores the importance of sophisticated User Agent management in distinguishing legitimate scraping activities from those that might be harmful to web servers.

Puppeteer, an open-source browser automation library developed by Google, has emerged as a powerful tool for web scraping due to its ability to control headless Chrome or Chromium browsers programmatically. When combined with effective User Agent management strategies, Puppeteer can significantly enhance the success rate of web scraping projects by reducing the likelihood of detection and blocking.

In this comprehensive exploration of User Agent management in Puppeteer, we will delve into the importance of User Agent manipulation, advanced techniques for rotation and management, and best practices for implementing these strategies in real-world scenarios. We will also address the challenges faced in User Agent-based scraping and provide insights into overcoming these obstacles.

By mastering the art of User Agent management in Puppeteer, developers and data scientists can create more resilient, efficient, and ethical web scraping solutions that can navigate the complex landscape of modern websites while respecting their terms of service and maintaining a low profile. As we proceed, we will uncover the nuances of this critical aspect of web scraping, equipping you with the knowledge and techniques necessary to optimize your data extraction processes in an increasingly challenging digital environment.

Puppeteer Local Storage: Set, Save and Restore Before Load

· 12 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Puppeteer Local Storage: Set, Save and Restore Before Load

Updated 2026-09-27

Replaced broken advanced examples and unsupported performance claims with a tested Chrome packet covering startup timing, state restoration, origin errors and extracted records. See the captured results.

Use page.evaluate() to read or change localStorage in an already loaded Puppeteer page. To supply a value before the application's scripts run, install an origin-guarded page.evaluateOnNewDocument() callback before navigation. Pass values as arguments; a function executing in the page cannot implicitly use your Node.js variables or helpers.

Then check the data you meant to extract. Our catalog returned four rows with a captured HTTP 200 status in every extraction observation, yet 15 of the 36 observations contained the deliberately selected wrong dataset. A successful write to localStorage was not enough to update the page.

How to Set Cookies in Puppeteer

· 12 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

How to Set Cookies in Puppeteer

In the realm of web automation and testing, Puppeteer has emerged as a powerful tool for developers and QA engineers. One crucial aspect of web interactions is the management of cookies, which play a vital role in maintaining user sessions, personalizing experiences, and handling authentication. This comprehensive guide delves into the intricacies of setting cookies in Puppeteer using JavaScript, exploring various methods and best practices to enhance your web automation projects.

Cookies are small pieces of data stored by websites on a user's browser, serving as a memory for web applications. In Puppeteer, manipulating these cookies programmatically allows for sophisticated automation scenarios, from maintaining login states to testing complex user flows. As web applications become increasingly complex, the ability to effectively manage cookies in automated environments has become a critical skill for developers.

This article will explore the fundamental methods for setting cookies in Puppeteer, including the versatile page.setCookie() function and the context-wide context.addCookies() method. We'll also delve into advanced techniques for cookie persistence, handling secure and HttpOnly cookies, and managing cookie expiration and deletion. Additionally, we'll cover best practices and advanced techniques that will elevate your cookie management skills, ensuring your Puppeteer scripts are robust, secure, and efficient.

By mastering these techniques, developers can create more reliable and sophisticated web automation solutions, capable of handling complex authentication flows, maintaining long-running sessions, and accurately simulating user interactions across various web applications. Whether you're building automated testing suites, web scrapers, or complex browser-based tools, understanding the nuances of cookie management in Puppeteer is essential for success in modern web development landscapes.

As we explore these topics, we'll provide detailed code samples and explanations, ensuring that both beginners and experienced developers can enhance their Puppeteer skills and create more powerful, efficient, and secure web automation solutions.

Looking for Playwright? Check out our guide on How to Set Cookies in Playwright.

Avoid Detection with Puppeteer Stealth

· 7 min read
Satyam Tripathi
Satyam is a junior data engineer and seasoned blogger. He has created several top-ranked tutorials on different topics like web scraping, automation, and scraping tools. He is always open to working with new technologies in the market and sharing his knowledge.

Avoid Detection with Puppeteer Stealth

Puppeteer is a powerful Node.js library that provides a high-level API for controlling browsers through the DevTools Protocol. It is commonly used for testing, web scraping, and automating repetitive browser tasks. However, Puppeteer's default settings can trigger bot detection systems, especially in headless mode.

Playwright vs. Puppeteer in 2024 - Which Should You Choose?

· 9 min read
Satyam Tripathi
Satyam is a junior data engineer and seasoned blogger. He has created several top-ranked tutorials on different topics like web scraping, automation, and scraping tools. He is always open to working with new technologies in the market and sharing his knowledge.

Playwright vs. Puppeteer in 2024: Which Should You Choose?

In the ever-evolving landscape of web automation and testing, two tools have consistently stood out: Playwright and Puppeteer. As of 2024, both have matured significantly, offering robust features for developers and testers alike. Both tools, developed by teams at Microsoft and Google respectively, offer robust solutions for automating browser tasks, but they cater to slightly different needs and preferences.

How to submit a form with Puppeteer?

· 13 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

How to submit a form with Puppeteer?

Puppeteer, a Node.js library developed by Google, offers a high-level API to control headless Chrome or Chromium browsers, making it an indispensable tool for web scraping, automated testing, and form submission automation. In today's digital landscape, automating form submissions is crucial for a variety of applications, ranging from data collection to user interaction testing. Puppeteer provides a robust solution for these tasks, allowing developers to programmatically interact with web pages as if they were using a regular browser. This guide delves into the setup and advanced techniques for using Puppeteer to automate form submissions, ensuring reliable and efficient automation processes. By following the outlined steps, users can install and configure Puppeteer, create basic scripts, handle dynamic form elements, manage complex inputs, and integrate with testing frameworks like Jest. Additionally, this guide explores effective strategies for bypassing CAPTCHAs and anti-bot measures, which are common obstacles in web automation.

Looking for a Playwright guide? Check out: How to submit a form with Playwright?