NEWScrapingAnt MCP for Claude Code, Cursor & Windsurf — try it free →
Skip to main content

252 posts tagged with "data extraction"

View All Tags

HTML vs Markdown vs Plain Text for LLM Extraction

· 19 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

HTML vs Markdown vs Plain Text for LLM Extraction

Choose the smallest representation that preserves the information your extraction task needs. Plain text can be sufficient for visible values. Markdown is a useful candidate when headings, tables and link destinations matter. Keep HTML when the answer depends on DOM attributes or script data that conversion removes.

We tested the same six-field extraction contract on three saved inputs, then on 15 hosted MCP returns. HTML produced correct records in each tested case. Markdown worked for the purchase-link case but returned empty arrays for the table. Local text worked for the table; hosted raw-mode text did not. These small, fixed-model results make the practical rule sharper: preserve the fields, then validate complete records before comparing cost.

Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

· 13 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

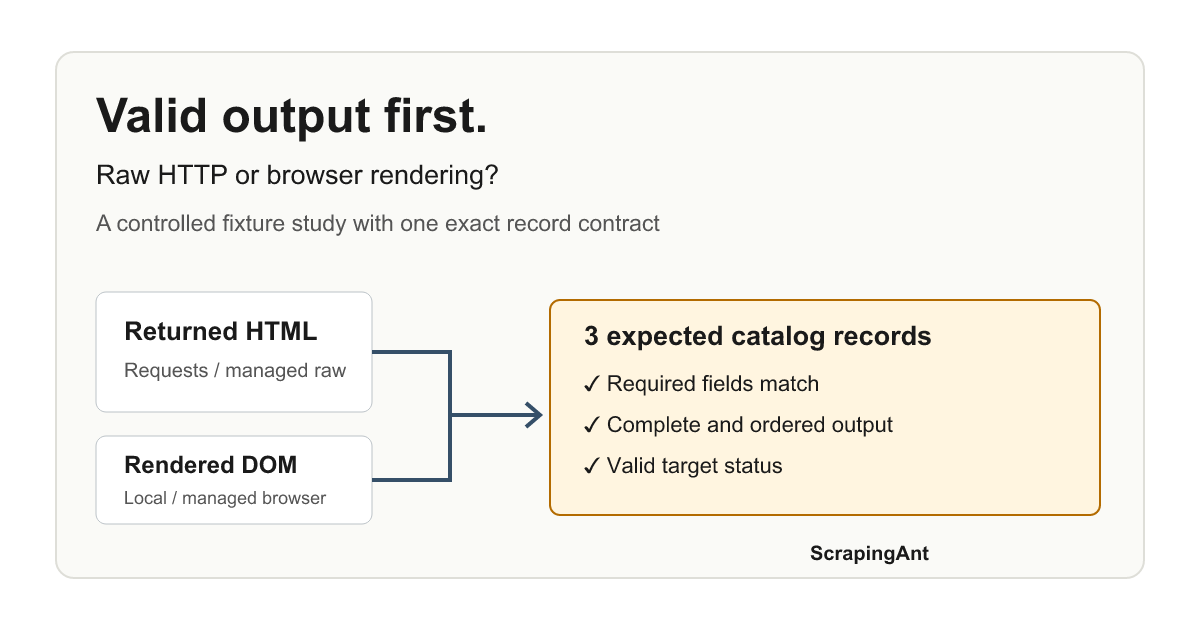
Choose a scraping method by the records it delivers. A fast response containing a loading placeholder cannot satisfy a price-monitoring job. A browser may add unnecessary work when the required table is already in the HTML.

The recorded benchmark compared Python Requests, direct Playwright and both ScrapingAnt modes against two controlled, already published fixtures. All four extracted the static catalog correctly. Only the browser arms passed the delayed JavaScript diagnostic. For the catalog, ScrapingAnt raw delivered the same validated records for 90% fewer API credits than ScrapingAnt rendered: 0.3333 credits per accepted record observation, versus 3.3333 credits with rendering. Direct Requests and Playwright had lower observed latency; their total operating cost was not measured.

Find Elements with Playwright in Python: Extract Validated Records

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Find Elements with Playwright in Python: Extract Validated Records

Use page.locator("#catalog > .product") to find repeated elements in Python Playwright. Narrow to an intended record before reading a single value, or call all() to iterate the matches after the list has finished loading. To build records in the browser, use evaluate_all() with a JavaScript projection.

Finding a match is only part of extraction. In the examples below, .first returned a sponsored product, while an early count() found a loading placeholder. Both operations worked; both selected the wrong data. The runnable example waits for the catalog's ready state and checks every SKU, title, currency, price and link against independently specified records.

Puppeteer Find Elements: Select, Wait and Extract Records

· 14 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Puppeteer Find Elements: Select, Wait and Extract Records

Use page.$() to get the first matching element and page.$$() to get all matching elements. When you want data rather than handles, page.$eval() runs a callback on the first match, and page.$$eval() passes all matches to a callback that can return JSON records.

The selector still needs to identify the right records, and the fields must be populated before you read them. This guide demonstrates both problems with a local catalogue: a promotional card that matches an overly broad selector, and product cards that exist before their titles and prices arrive.

Test a Production Scraper: Retries, Timeouts and Invalid Data

· 9 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Test a Production Scraper: Retries, Timeouts and Invalid Data

Correction (2026-09-29)

The earlier article included unsupported avoidance, uptime, anti-bot prevalence and vendor-comparison claims. Those claims have been removed. This refresh replaces the broad recommendations with an executed local failure harness, including incorrect records that passed validation and a deadline that overran under host load. No production-site reliability benchmark is claimed.

A scraper returning HTTP 200 can still produce an empty page, malformed data or the wrong price. Before connecting it to a downstream dataset, test what it does when retrieval, extraction, validation and storage fail separately.

The Python example below runs against an owned, local catalog. It checks retry limits, timeouts, record validation and duplicate delivery. Its most useful result is a failure of the data checks: three deliberately wrong prices passed the schema and reached storage.

Top Google Alternatives for Web Scraping in 2025

· 8 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Top Google Alternatives for Web Scraping in 2025

Teams that depend on SERP data for competitive intelligence, content research, or data extraction increasingly look beyond Google because HTML pages are volatile, highly personalized, and protected by advanced anti-bot systems—issues that raise cost, legal risk, and maintenance burden for scrapers. The 2025 landscape favors an API-first approach with alternative search engines that return stable, structured JSON (or XML) and clear terms, making pipelines more reliable and compliant for SEO analytics and web data extraction.

Among general-purpose options, Microsoft’s Bing remains the most practical choice for production pipelines due to its mature multi-vertical Web, Image, Video, and News endpoints, robust localization, and predictable quotas via the Azure-hosted Bing Web Search API (Bing Web Search API). For teams that value an independent index with strong privacy posture, the Brave Search API provides web, images, and news in well-structured JSON and plan-based quotas.

Privacy-first and lightweight use cases sometimes start with DuckDuckGo. While it does not expose a full web search API, its Instant Answer (IA) API can power specific knowledge lookups, and its minimalist HTML endpoint is simple to parse at modest volumes—always within policy and with conservative rate limits (DuckDuckGo Instant Answer API, DuckDuckGo parameters). When you need a controllable gateway that aggregates multiple engines into a single JSON format, self-hosted SearXNG is a strong option; just remember that you—not SearXNG—are responsible for complying with each backend’s terms (SearXNG docs).

Decentralized Web Scraping and Data Extraction with YaCy

· 23 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Decentralized Web Scraping and Data Extraction with YaCy

Running your own search engine for web scraping and data extraction is no longer the domain of hyperscalers. YaCy - a mature, peer‑to‑peer search engine - lets teams build privacy‑preserving crawlers, indexes, and search portals on their own infrastructure. Whether you are indexing a single site, an intranet, or contributing to the open web, YaCy’s modes and controls make it adaptable: use Robinson Mode for isolated/private crawling, or participate in the P2P network when you intend to share index fragments.

In this report, we present a practical, secure, and scalable approach for operating YaCy as the backbone of compliant web scraping and data extraction. At the network edge, you can place a reverse proxy such as Caddy to centralize TLS, authentication, and rate limiting, while keeping the crawler nodes private. For maximum privacy, you can gate all access through a VPN using WireGuard so that YaCy and your data pipelines are reachable only by authenticated peers. We compare these patterns and show how to combine them: run Caddy publicly only when you need an HTTPS endpoint (for dashboards or APIs), and backhaul securely to private crawler nodes over WireGuard.

Connecting Playwright MCP to Proxy Servers

· 4 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Connecting Playwright MCP to Proxy Servers

The integration of Playwright MCP (Model Context Protocol) with proxy servers represents a significant advancement. Playwright MCP, a robust framework that combines browser automation with large language models (LLMs), offers a powerful solution for automating web interactions. This integration is particularly beneficial for tasks that require executing JavaScript, taking screenshots, and navigating web elements in a real browser environment.

The role of proxies in this setup cannot be overstated. Proxies enhance the functionality and security of Playwright MCP by allowing access to geo-specific content, ensuring privacy by masking IP addresses, and simulating network scenarios for testing. This is crucial for organizations that require secure and compliant network setups, adhering to enterprise security protocols (ScrapingAnt). As the demand for sophisticated web scraping and data extraction tools grows, understanding how to effectively configure and manage proxies within Playwright MCP becomes essential for developers and businesses alike.

The Importance of Web Scraping and Data Extraction for Military Operations

· 7 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

The Importance of Web Scraping and Data Extraction for Military Operations

Web scraping is instrumental in identifying threats and vulnerabilities that could impact national security. By extracting data from hacker forums and dark web marketplaces, military intelligence agencies can gain valuable insights into cybercriminal activities and emerging threats (CyberScoop). This capability is crucial for maintaining a robust defense posture and ensuring national security. Additionally, web scraping allows for the monitoring of geopolitical developments, providing military strategists with a comprehensive view of the operational environment and enabling informed decision-making.

The integration of web-scraped data into military cybersecurity operations further underscores its importance. By automating data extraction techniques, military cybersecurity teams can efficiently monitor various online platforms to gain insights into emerging threats and adversarial tactics (SANS Institute). This proactive approach helps in detecting threats before they materialize, providing a strategic advantage in defending against cyber espionage and sabotage. However, the use of web scraping also raises ethical and legal considerations, necessitating careful navigation of legal boundaries to ensure responsible data collection and maintain public trust.

Compliance and Risk Management in Automated Data Extraction - Frameworks, Technologies, and Best Practices

· 16 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Compliance and Risk Management in Automated Data Extraction

Organizations face increasing scrutiny from regulatory bodies, with stringent laws such as the General Data Protection Regulation (GDPR) and the European Union's Artificial Intelligence Act (AI Act) imposing heavy penalties for non-compliance. For instance, GDPR violations can result in fines up to 4% of annual global turnover, highlighting the critical importance of adhering to compliance standards (ComplyDog, 2025).

Moreover, the evolving regulatory landscape demands that businesses not only comply with existing laws but also proactively adapt to emerging regulations governing AI and automated data extraction. Technologies such as AI, machine learning, blockchain, and cloud-based solutions are increasingly leveraged to automate compliance processes, significantly reducing operational costs and legal risks. For example, AI-driven compliance tools can reduce manual compliance costs by up to 60%, providing substantial ROI for businesses (Akkio).

Effective data governance frameworks and risk management strategies are essential to navigate these complexities. Organizations implementing robust governance practices typically experience a 30-40% reduction in compliance incidents and a 25% improvement in data quality, directly translating into cost savings and enhanced operational efficiency (Atlan, 2025). Specialized web scraping services like ScrapingAnt further address legal concerns by providing compliant scraping solutions, including proxy rotation, IP masking, and adherence to website terms of service, significantly mitigating legal risks associated with unauthorized data extraction (ScrapingAnt).

This research report explores the regulatory landscape, technological advancements, and best practices in compliance and risk management for automated data collection, providing actionable insights and technical implementation details to help organizations achieve compliant, efficient, and cost-effective web scraping operations.