NEWScrapingAnt MCP for Claude Code, Cursor & Windsurf — try it free →
Skip to main content

259 posts tagged with "web scraping"

View All Tags

Railway, GitLab, LiteLLM Breaches: How to Rotate API Keys

· 8 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Railway, GitLab, LiteLLM Breaches: How to Rotate API Keys

October 2026 has been a rough month for anyone who keeps API keys in the cloud. In a single week, a hosting platform reported that environment variables were decrypted by an intruder, GitLab shipped emergency fixes for a CVSS 10.0 remote code execution bug, and a popular Python package published a release that stole credentials from every machine that installed it.

If your scrapers, data pipelines or CI jobs touched any of these, assume the keys they held are exposed and rotate them. Below is a short summary of each incident from the vendors' own reports, a practical rotation checklist, and exact steps to reset your ScrapingAnt API key and proxy credentials.
HTML vs Markdown vs Plain Text for LLM Extraction

· 19 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

HTML vs Markdown vs Plain Text for LLM Extraction

Choose the smallest representation that preserves the information your extraction task needs. Plain text can be sufficient for visible values. Markdown is a useful candidate when headings, tables and link destinations matter. Keep HTML when the answer depends on DOM attributes or script data that conversion removes.

We tested the same six-field extraction contract on three saved inputs, then on 15 hosted MCP returns. HTML produced correct records in each tested case. Markdown worked for the purchase-link case but returned empty arrays for the table. Local text worked for the table; hosted raw-mode text did not. These small, fixed-model results make the practical rule sharper: preserve the fields, then validate complete records before comparing cost.

Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

· 13 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

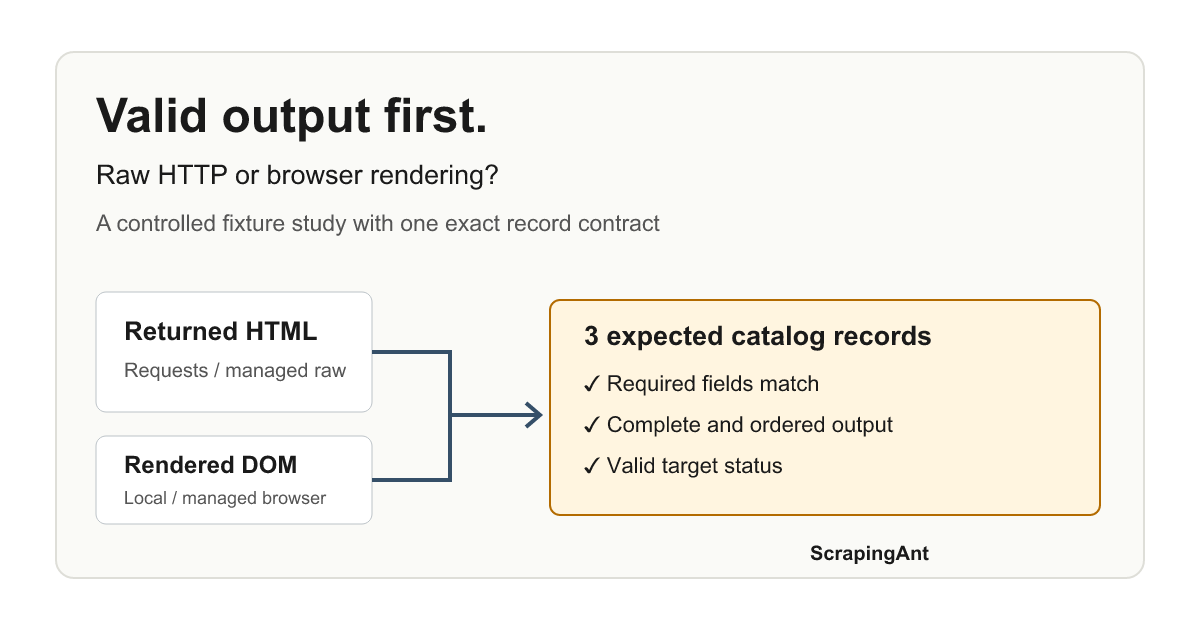
Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

Choose a scraping method by the records it delivers. A fast response containing a loading placeholder cannot satisfy a price-monitoring job. A browser may add unnecessary work when the required table is already in the HTML.

The recorded benchmark compared Python Requests, direct Playwright and both ScrapingAnt modes against two controlled, already published fixtures. All four extracted the static catalog correctly. Only the browser arms passed the delayed JavaScript diagnostic. For the catalog, ScrapingAnt raw delivered the same validated records for 90% fewer API credits than ScrapingAnt rendered: 0.3333 credits per accepted record observation, versus 3.3333 credits with rendering. Direct Requests and Playwright had lower observed latency; their total operating cost was not measured.

Apify Pricing: Reconcile Actor Charges and Platform Usage

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Apify Pricing: Reconcile Actor Charges and Platform Usage

Updated October 7, 2026

Added observed Website Content Crawler runs on 30 owned synthetic pages to demonstrate cost per accepted output. The dated observation CSV preserves full-precision inputs. The seven offline ledgers remain synthetic, and their pricing snapshot remains dated October 2.

Apify's monthly Starter plan is $19 with $19 of prepaid usage. That does not mean every Actor costs $19, or that its event price always has compute and proxy charges added on top. The chosen Actor's charging model determines which line items consume that allowance.

This guide starts with the current prices, then provides an offline charge-reconciliation worksheet. It helps you add known charges once and expose missing inputs. All seven example ledgers are synthetic: their Actor IDs, versions, consumption and accepted-record counts are invented test inputs. A separate worked example uses observed Actor runs on owned synthetic pages. Neither set is a customer invoice. ScrapingAnt publishes this article and sells a competing retrieval API.

Firecrawl Pricing: Budget for Accepted Results

· 12 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Firecrawl Pricing: Budget for Accepted Results

Firecrawl's basic scrape costs one credit per page. Your useful unit is the result your application can accept: a complete record, rendered content, or a table with the correct cell associations. Budgeting from successful HTTP responses alone misses that difference.

This guide answers the plan-price question first, then models a recurring URL list and explains a 200-credit controlled study. The study used free credits; it measured credit consumption, not cash expenditure. ScrapingAnt publishes this article and sells a competing retrieval API. There is no ScrapingAnt head-to-head test here.

Find Elements with Playwright in Python: Extract Validated Records

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

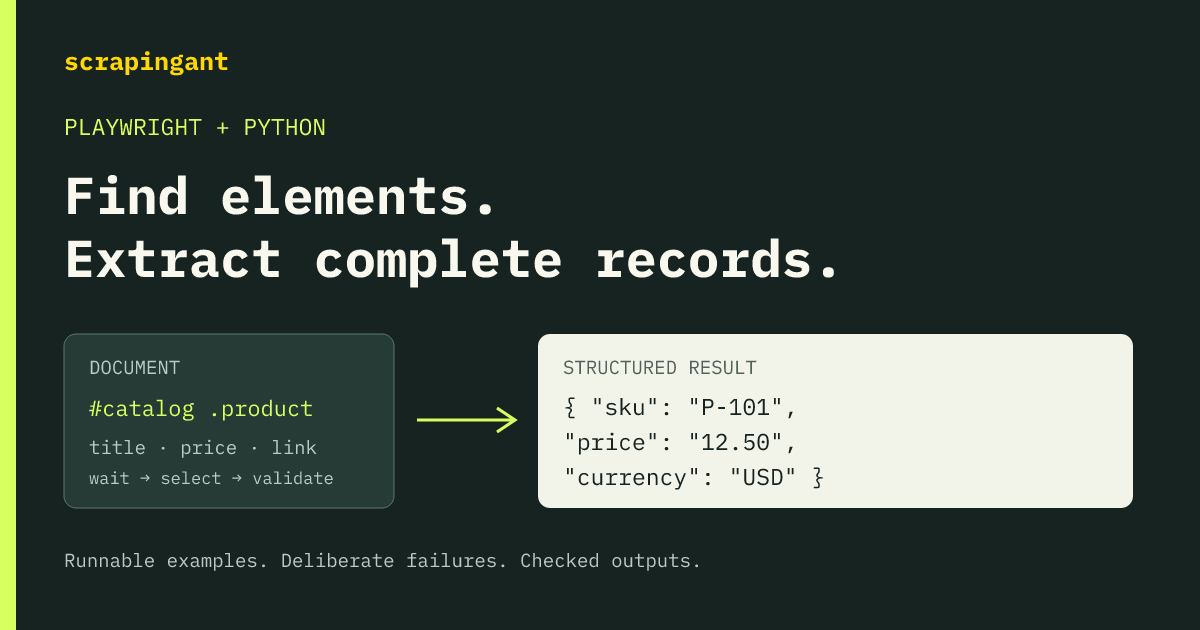
Find Elements with Playwright in Python: Extract Validated Records

Use page.locator("#catalog > .product") to find repeated elements in Python Playwright. Narrow to an intended record before reading a single value, or call all() to iterate the matches after the list has finished loading. To build records in the browser, use evaluate_all() with a JavaScript projection.

Finding a match is only part of extraction. In the examples below, .first returned a sponsored product, while an early count() found a loading placeholder. Both operations worked; both selected the wrong data. The runnable example waits for the catalog's ready state and checks every SKU, title, currency, price and link against independently specified records.

Puppeteer Find Elements: Select, Wait and Extract Records

· 14 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Puppeteer Find Elements: Select, Wait and Extract Records

Use page.$() to get the first matching element and page.$$() to get all matching elements. When you want data rather than handles, page.$eval() runs a callback on the first match, and page.$$eval() passes all matches to a callback that can return JSON records.

The selector still needs to identify the right records, and the fields must be populated before you read them. This guide demonstrates both problems with a local catalogue: a promotional card that matches an overly broad selector, and product cards that exist before their titles and prices arrive.

Collect Employer Job Postings with Python and ScrapingAnt

· 12 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Collect Employer Job Postings with Python and ScrapingAnt

Updated 2026-10-12 — publication approved by Oleg Kulyk

This draft replaces broad labor-market and scraping-provider claims with a bounded job-posting collector, captured fixtures and explicit limits. The original URL, publication date and banner are preserved. Download the reproducibility packet.

A job-posting refresh needs more than a list of titles. It needs stable posting IDs, source URLs, validated fields, and a way to distinguish a complete collection from a failed second page. Otherwise, a transient failure can turn into a false disappearance alert.

This walkthrough collects one employer listing that you are authorized to access. The runnable pagination and refresh example uses a fictional, owned careers site. Separate evidence includes an official Greenhouse JSON alternative and one accepted raw managed retrieval of a selected published Greenhouse posting. ScrapingAnt is an optional HTML transport; parsing and validation remain explicit Python code.

Test a Production Scraper: Retries, Timeouts and Invalid Data

· 9 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Test a Production Scraper: Retries, Timeouts and Invalid Data

Correction (2026-09-29)

The earlier article included unsupported avoidance, uptime, anti-bot prevalence and vendor-comparison claims. Those claims have been removed. This refresh replaces the broad recommendations with an executed local failure harness, including incorrect records that passed validation and a deadline that overran under host load. No production-site reliability benchmark is claimed.

A scraper returning HTTP 200 can still produce an empty page, malformed data or the wrong price. Before connecting it to a downstream dataset, test what it does when retrieval, extraction, validation and storage fail separately.

The Python example below runs against an owned, local catalog. It checks retry limits, timeouts, record validation and duplicate delivery. Its most useful result is a failure of the data checks: three deliberately wrong prices passed the schema and reached storage.