NEWScrapingAnt MCP for Claude Code, Cursor & Windsurf — try it free →
Skip to main content

Web Scraping Blog

HTML vs Markdown vs Plain Text for LLM Extraction

· 19 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

HTML vs Markdown vs Plain Text for LLM Extraction

Choose the smallest representation that preserves the information your extraction task needs. Plain text can be sufficient for visible values. Markdown is a useful candidate when headings, tables and link destinations matter. Keep HTML when the answer depends on DOM attributes or script data that conversion removes.

We tested the same six-field extraction contract on three saved inputs, then on 15 hosted MCP returns. HTML produced correct records in each tested case. Markdown worked for the purchase-link case but returned empty arrays for the table. Local text worked for the table; hosted raw-mode text did not. These small, fixed-model results make the practical rule sharper: preserve the fields, then validate complete records before comparing cost.
Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

· 13 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

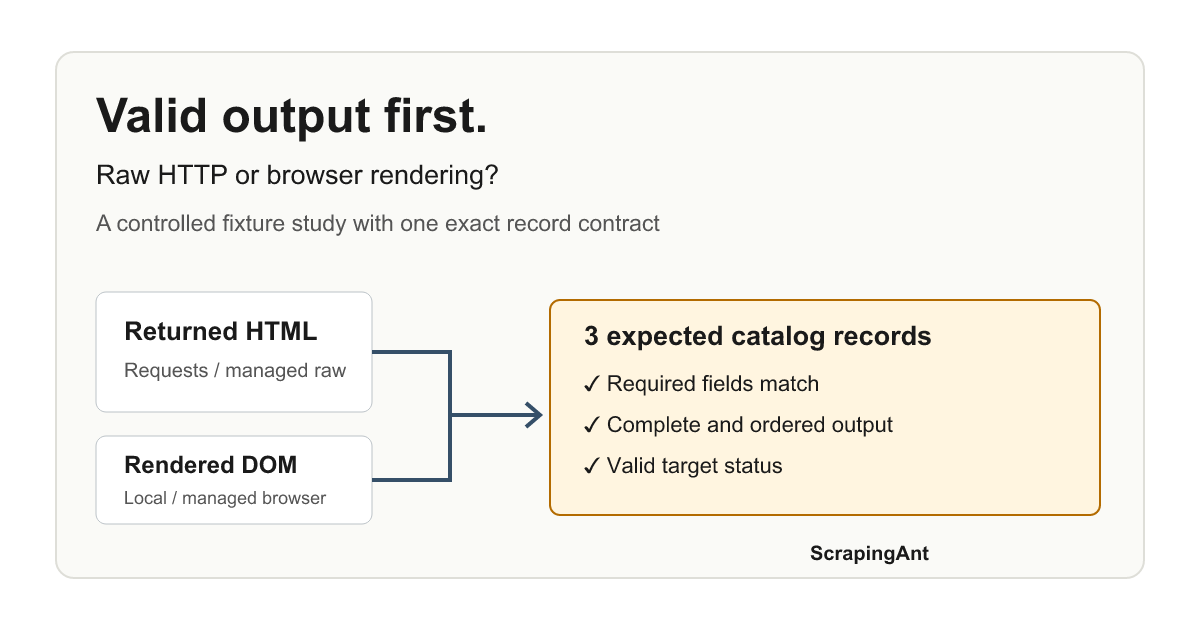
Choose a scraping method by the records it delivers. A fast response containing a loading placeholder cannot satisfy a price-monitoring job. A browser may add unnecessary work when the required table is already in the HTML.

The recorded benchmark compared Python Requests, direct Playwright and both ScrapingAnt modes against two controlled, already published fixtures. All four extracted the static catalog correctly. Only the browser arms passed the delayed JavaScript diagnostic. For the catalog, ScrapingAnt raw delivered the same validated records for 90% fewer API credits than ScrapingAnt rendered: 0.3333 credits per accepted record observation, versus 3.3333 credits with rendering. Direct Requests and Playwright had lower observed latency; their total operating cost was not measured.

Apify Pricing: Reconcile Actor Charges and Platform Usage

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Apify Pricing: Reconcile Actor Charges and Platform Usage

Updated October 7, 2026

Added observed Website Content Crawler runs on 30 owned synthetic pages to demonstrate cost per accepted output. The dated observation CSV preserves full-precision inputs. The seven offline ledgers remain synthetic, and their pricing snapshot remains dated October 2.

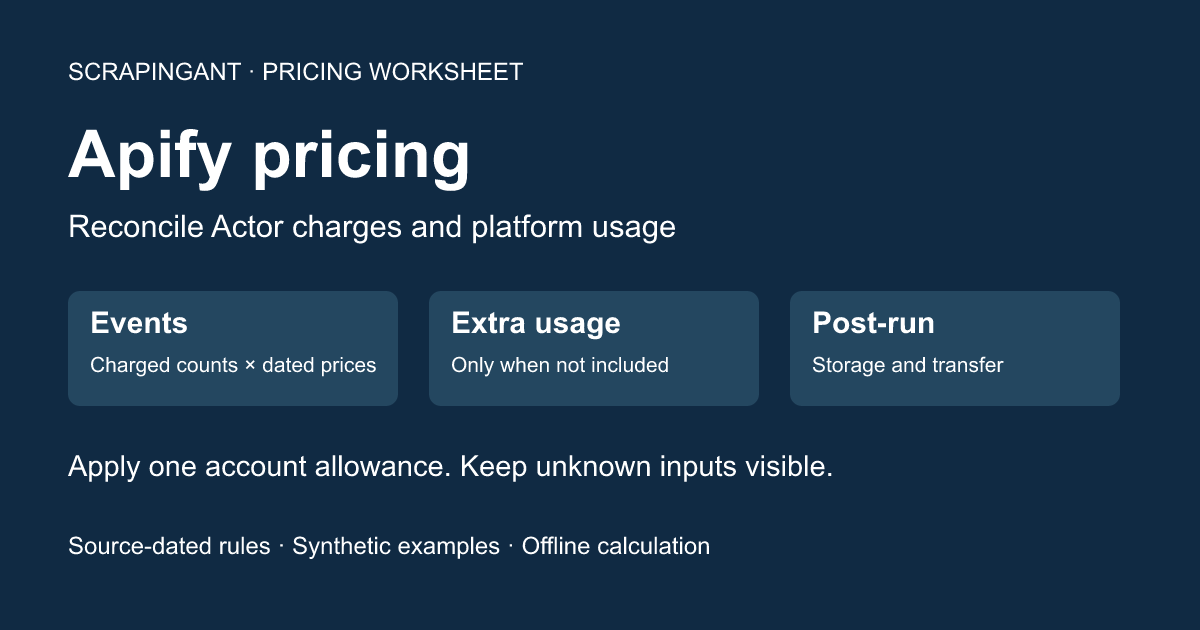
Apify's monthly Starter plan is $19 with $19 of prepaid usage. That does not mean every Actor costs $19, or that its event price always has compute and proxy charges added on top. The chosen Actor's charging model determines which line items consume that allowance.

This guide starts with the current prices, then provides an offline charge-reconciliation worksheet. It helps you add known charges once and expose missing inputs. All seven example ledgers are synthetic: their Actor IDs, versions, consumption and accepted-record counts are invented test inputs. A separate worked example uses observed Actor runs on owned synthetic pages. Neither set is a customer invoice. ScrapingAnt publishes this article and sells a competing retrieval API.

Firecrawl Pricing: Budget for Accepted Results

· 12 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Firecrawl Pricing: Budget for Accepted Results

Firecrawl's basic scrape costs one credit per page. Your useful unit is the result your application can accept: a complete record, rendered content, or a table with the correct cell associations. Budgeting from successful HTTP responses alone misses that difference.

This guide answers the plan-price question first, then models a recurring URL list and explains a 200-credit controlled study. The study used free credits; it measured credit consumption, not cash expenditure. ScrapingAnt publishes this article and sells a competing retrieval API. There is no ScrapingAnt head-to-head test here.

Find Elements with Playwright in Python: Extract Validated Records

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Find Elements with Playwright in Python: Extract Validated Records

Use page.locator("#catalog > .product") to find repeated elements in Python Playwright. Narrow to an intended record before reading a single value, or call all() to iterate the matches after the list has finished loading. To build records in the browser, use evaluate_all() with a JavaScript projection.

Finding a match is only part of extraction. In the examples below, .first returned a sponsored product, while an early count() found a loading placeholder. Both operations worked; both selected the wrong data. The runnable example waits for the catalog's ready state and checks every SKU, title, currency, price and link against independently specified records.

Puppeteer Find Elements: Select, Wait and Extract Records

· 14 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Puppeteer Find Elements: Select, Wait and Extract Records

Use page.$() to get the first matching element and page.$$() to get all matching elements. When you want data rather than handles, page.$eval() runs a callback on the first match, and page.$$eval() passes all matches to a callback that can return JSON records.

The selector still needs to identify the right records, and the fields must be populated before you read them. This guide demonstrates both problems with a local catalogue: a promotional card that matches an overly broad selector, and product cards that exist before their titles and prices arrive.

From HTML to Embeddings - ML-Based Parsers That Survive Layout Changes

· 16 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

From HTML to Embeddings: ML-Based Parsers That Survive Layout Changes

Correction (2026-09-14)

An earlier version of this article claimed that ML parsers achieve "F1 improvements of 10–25 percentage points over rule-based baselines under layout changes" and "F1 above 0.9 in field deployments" without identifying a source. We could not trace either number to a published experiment. Sections 4.1 and 5.3 now cite the SWDE few-shot results from Li et al. (ACL 2022) and state what those results do and do not show.

Traditional web scraping pipelines rely heavily on brittle, hand-crafted rules – CSS selectors, XPath queries, and regular expressions – that tend to break as soon as a website’s layout or DOM structure changes. With the rapid evolution of front-end frameworks, A/B testing, and personalized content, these brittle approaches impose high maintenance costs and limit scalability.

Healthcare Market Mapping - Scraping Provider Networks and Formularies

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Healthcare Market Mapping: Scraping Provider Networks and Formularies

Healthcare market mapping increasingly depends on granular, up‑to‑date data on provider networks and drug formularies. Payers, health systems, digital health companies, and analytics firms use these data to understand network adequacy, competitive positioning, product design, and patient access. However, much of this information is not available via clean, official APIs; instead, it resides in heterogeneous, JavaScript-heavy web portals that were built for human browsing, not machine consumption.

LLM-Assisted Robots.txt Reasoning - Dynamic Crawl Policies Per Use Case

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

LLM-Assisted Robots.txt Reasoning: Dynamic Crawl Policies Per Use Case

Correction (2026-09-14)

An earlier version of this article stated that the Robots Exclusion Protocol was never standardized as an IETF RFC and that Google's 2019 proposal was withdrawn. That was incorrect: the protocol was published as RFC 9309, an IETF Standards Track document, in September 2022. The "Background" section below has been corrected.

Robots.txt has long been the core mechanism for expressing crawl preferences and constraints on the web. Yet, the file format is intentionally simple and underspecified, while real-world websites exhibit complex, context-dependent expectations around crawling, scraping, and automated interaction. In parallel, large language models (LLMs) and agentic AI workflows are transforming how scraping systems reason about and adapt to such expectations.