NEWScrapingAnt MCP for Claude Code, Cursor & Windsurf — try it free →
Skip to main content

73 posts tagged with "python"

View All Tags

Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

· 13 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

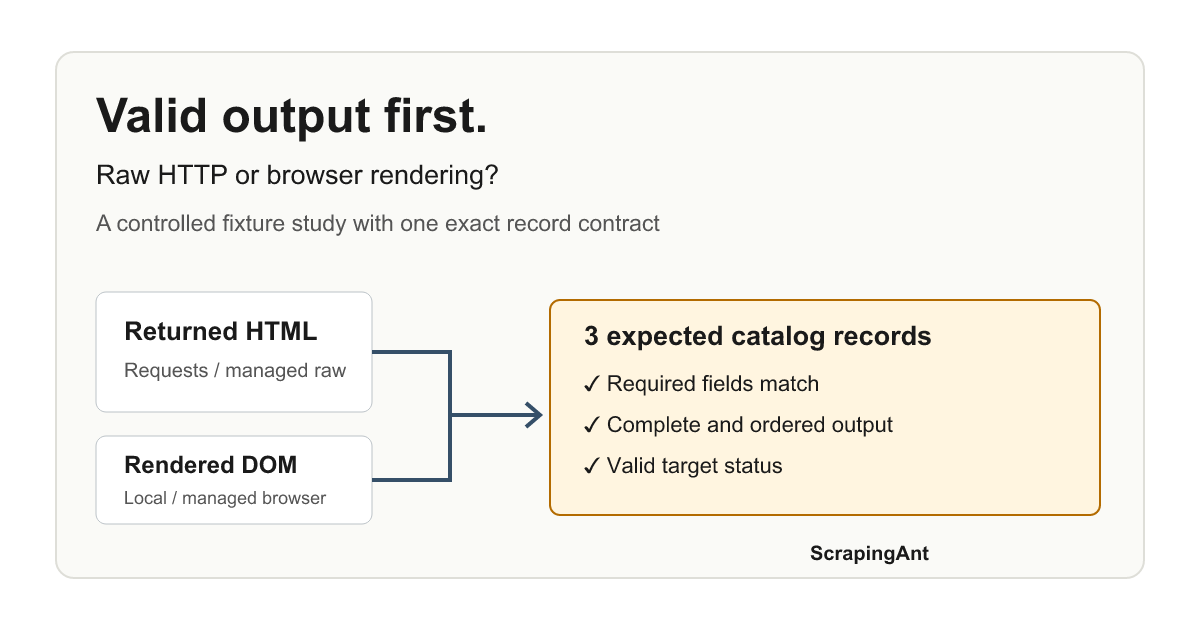
Choose a scraping method by the records it delivers. A fast response containing a loading placeholder cannot satisfy a price-monitoring job. A browser may add unnecessary work when the required table is already in the HTML.

The recorded benchmark compared Python Requests, direct Playwright and both ScrapingAnt modes against two controlled, already published fixtures. All four extracted the static catalog correctly. Only the browser arms passed the delayed JavaScript diagnostic. For the catalog, ScrapingAnt raw delivered the same validated records for 90% fewer API credits than ScrapingAnt rendered: 0.3333 credits per accepted record observation, versus 3.3333 credits with rendering. Direct Requests and Playwright had lower observed latency; their total operating cost was not measured.
Find Elements with Playwright in Python: Extract Validated Records

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Find Elements with Playwright in Python: Extract Validated Records

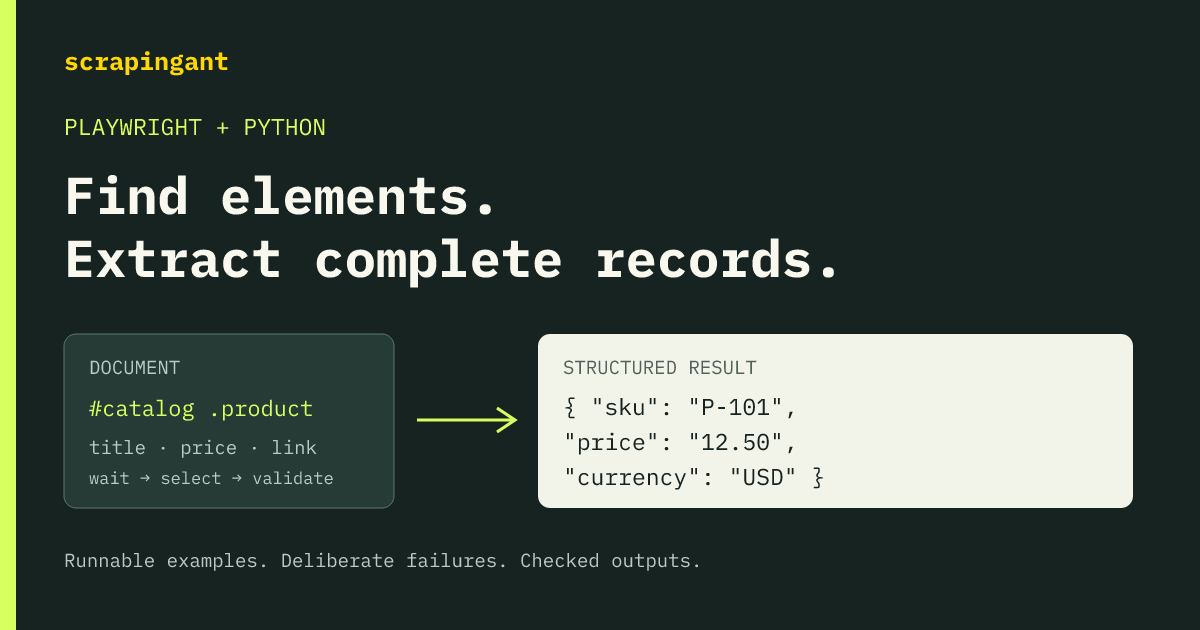
Use page.locator("#catalog > .product") to find repeated elements in Python Playwright. Narrow to an intended record before reading a single value, or call all() to iterate the matches after the list has finished loading. To build records in the browser, use evaluate_all() with a JavaScript projection.

Finding a match is only part of extraction. In the examples below, .first returned a sponsored product, while an early count() found a loading placeholder. Both operations worked; both selected the wrong data. The runnable example waits for the catalog's ready state and checks every SKU, title, currency, price and link against independently specified records.

Collect Employer Job Postings with Python and ScrapingAnt

· 12 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Collect Employer Job Postings with Python and ScrapingAnt

Updated 2026-10-12 — publication approved by Oleg Kulyk

This draft replaces broad labor-market and scraping-provider claims with a bounded job-posting collector, captured fixtures and explicit limits. The original URL, publication date and banner are preserved. Download the reproducibility packet.

A job-posting refresh needs more than a list of titles. It needs stable posting IDs, source URLs, validated fields, and a way to distinguish a complete collection from a failed second page. Otherwise, a transient failure can turn into a false disappearance alert.

This walkthrough collects one employer listing that you are authorized to access. The runnable pagination and refresh example uses a fictional, owned careers site. Separate evidence includes an official Greenhouse JSON alternative and one accepted raw managed retrieval of a selected published Greenhouse posting. ScrapingAnt is an optional HTML transport; parsing and validation remain explicit Python code.

Test a Production Scraper: Retries, Timeouts and Invalid Data

· 9 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Test a Production Scraper: Retries, Timeouts and Invalid Data

Correction (2026-09-29)

The earlier article included unsupported avoidance, uptime, anti-bot prevalence and vendor-comparison claims. Those claims have been removed. This refresh replaces the broad recommendations with an executed local failure harness, including incorrect records that passed validation and a deadline that overran under host load. No production-site reliability benchmark is claimed.

A scraper returning HTTP 200 can still produce an empty page, malformed data or the wrong price. Before connecting it to a downstream dataset, test what it does when retrieval, extraction, validation and storage fail separately.

The Python example below runs against an owned, local catalog. It checks retry limits, timeouts, record validation and duplicate delivery. Its most useful result is a failure of the data checks: three deliberately wrong prices passed the schema and reached storage.

How to Scrape Tripadvisor Data Using ScrapingAnt's Web Scraping API in Python

· 6 min read
Tanweer Ali
Tanweer Ali
I'm a technical writer with a background in software development who loves writing about data and automation software.

How to Scrape Tripadvisor Data Using ScrapingAnt's Web Scraping API in Python

Tripadvisor is without a doubt one of the biggest travel platforms out there travelers will consult to find out about the next hot summer destination.

It's a goldmine for user reviews and ratings of hotels, restaurants and vacation rentals.

In this short tutorial we will be scraping the names, reviews and standard prices of hotels in Python using ScrapingAnts Web Scraping API.

How to scrape dynamic websites with Scrapy Splash

· 8 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

How to scrape dynamic websites with Scrapy Splash

Handling dynamic websites with JavaScript-rendered content presents a significant challenge for traditional scraping tools. Scrapy Splash emerges as a powerful solution by combining the robust crawling capabilities of Scrapy with the JavaScript rendering prowess of the Splash headless browser. This comprehensive guide explores the integration and optimization of Scrapy Splash for effective dynamic website scraping.

Scrapy Splash has become an essential tool for developers and data scientists who need to extract data from JavaScript-heavy websites. The middleware (scrapy-plugins/scrapy-splash) seamlessly bridges Scrapy's asynchronous architecture with Splash's rendering engine, enabling the handling of complex web applications. This integration provides a robust foundation for handling modern web applications while maintaining high performance and reliability.

The system's architecture is specifically designed to handle the challenges of dynamic content rendering while ensuring efficient resource utilization.

Python Requests Cookies: Sessions, Scope and Scraped Data

· 12 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Python Requests Cookies: Sessions, Scope and Scraped Data

Updated 2026-09-27

Replaced untested persistence and recovery recipes with a runnable Requests cookie experiment. The new examples test redirect cookies, path collisions, prepared requests and session restoration against extracted records. Corrected unsupported cookie keyword arguments and the claim that mounting an HTTPS adapter forces HTTPS. The original URL, publication date and video are preserved.

Use a requests.Session() when later requests need cookies received earlier. Keep its cookie jar intact: a cookie is identified by more than its name, and a plain dictionary cannot represent two region cookies with different paths. For a single call, the cookies= parameter can supply cookies without making them persistent session state.

We tested those distinctions against a small catalog. A dictionary backup retained the member session but changed the selected currency from EUR to USD. The request returned HTTP 200 and all four expected product IDs. Only checking the currency and prices caught the wrong dataset.

This guide gives you a complete save/restore example and the failures behind it. The catalog, identities and prices are synthetic; the measurements demonstrate mechanisms, not success rates on real websites.

Web Scraping with VPN and Python

· 7 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Web Scraping with VPN and Python

Web scraping with VPN integration has become an essential practice in modern data collection strategies, combining the need for efficient data gathering with robust privacy and security measures. As organizations increasingly rely on web-based data for business intelligence and research, the implementation of VPN-enabled scraping solutions has evolved into a sophisticated technical domain. According to ScrapingAnt's implementation guide, the integration of VPNs with web scraping not only provides enhanced anonymity but also enables more reliable and sustainable data collection operations. The combination of Python's powerful scraping libraries with VPN technology creates a robust framework for handling large-scale data extraction while maintaining privacy and avoiding IP-based restrictions. Proper VPN implementation in web scraping projects has become crucial for maintaining consistent access to target websites while ensuring compliance with various access policies and restrictions. This research explores the technical implementations, best practices, and advanced techniques necessary for successfully combining VPN services with Python-based web scraping operations.

Web Scraping with Tor and Python

· 6 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Web Scraping with Tor and Python

Web scraping has become an essential tool for gathering information at scale. However, with increasing concerns about privacy and data collection restrictions, anonymous web scraping through the Tor network has emerged as a crucial methodology. This comprehensive guide explores the technical implementation and optimization of web scraping using Tor and Python, providing developers with the knowledge to build robust, anonymous data collection systems.

The integration of Tor with Python-based web scraping tools offers a powerful solution for maintaining anonymity while collecting data. Proper implementation of anonymous scraping techniques can significantly enhance privacy protection while maintaining efficient data collection capabilities. The combination of Tor's anonymity features with Python's versatile scraping libraries creates a framework that addresses both security concerns and performance requirements in modern web scraping applications.