NEWScrapingAnt MCP for Claude Code, Cursor & Windsurf — try it free →
Skip to main content

29 posts tagged with "playwright"

View All Tags

Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

· 13 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Requests vs Playwright vs ScrapingAnt: Cost per Valid Record

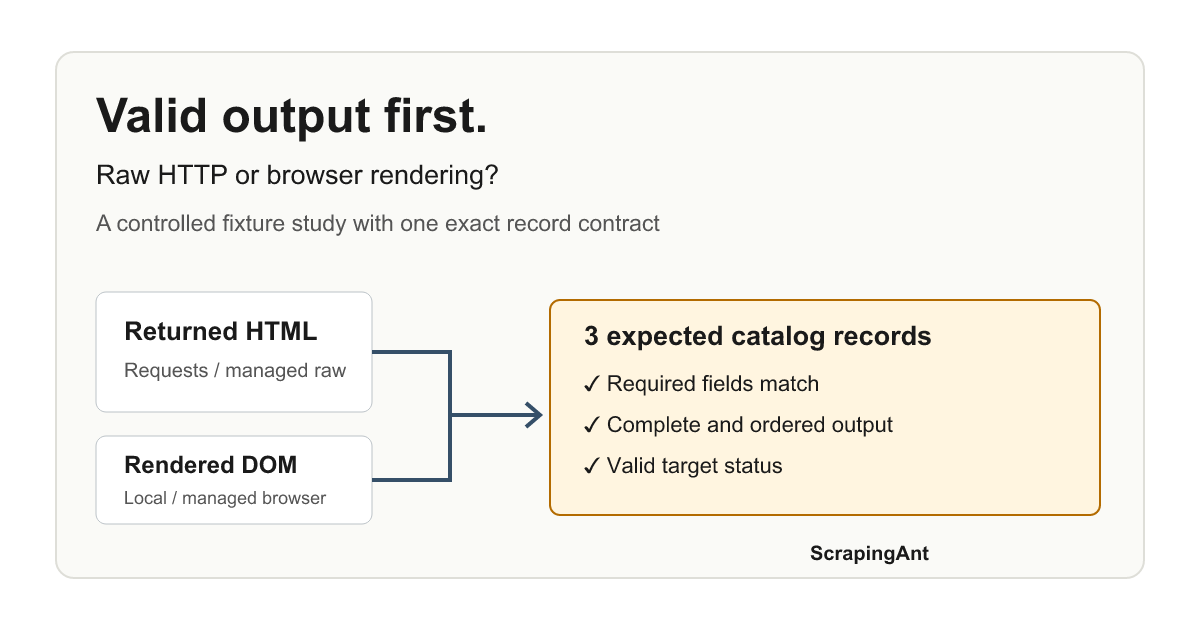
Choose a scraping method by the records it delivers. A fast response containing a loading placeholder cannot satisfy a price-monitoring job. A browser may add unnecessary work when the required table is already in the HTML.

The recorded benchmark compared Python Requests, direct Playwright and both ScrapingAnt modes against two controlled, already published fixtures. All four extracted the static catalog correctly. Only the browser arms passed the delayed JavaScript diagnostic. For the catalog, ScrapingAnt raw delivered the same validated records for 90% fewer API credits than ScrapingAnt rendered: 0.3333 credits per accepted record observation, versus 3.3333 credits with rendering. Direct Requests and Playwright had lower observed latency; their total operating cost was not measured.
Find Elements with Playwright in Python: Extract Validated Records

· 15 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Find Elements with Playwright in Python: Extract Validated Records

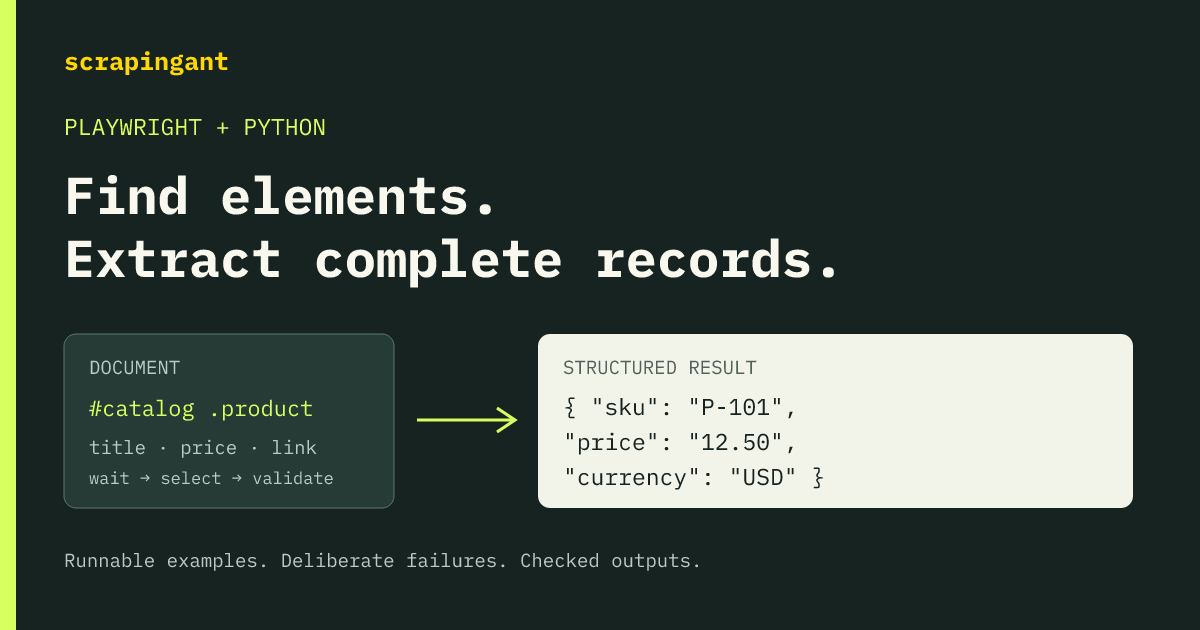
Use page.locator("#catalog > .product") to find repeated elements in Python Playwright. Narrow to an intended record before reading a single value, or call all() to iterate the matches after the list has finished loading. To build records in the browser, use evaluate_all() with a JavaScript projection.

Finding a match is only part of extraction. In the examples below, .first returned a sponsored product, while an early count() found a loading placeholder. Both operations worked; both selected the wrong data. The runnable example waits for the catalog's ready state and checks every SKU, title, currency, price and link against independently specified records.

How to Build a Web Scraper Using Playwright C#

· 7 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

How to Build a Web Scraper Using Playwright C#

Web scraping has become an essential tool in modern data extraction and automation workflows. Playwright, Microsoft's powerful browser automation framework, has emerged as a leading solution for robust web scraping implementations in C#. This comprehensive guide explores the implementation of web scraping using Playwright, offering developers a thorough understanding of its capabilities and best practices.

Playwright stands out in the automation landscape by offering multi-browser support and superior performance compared to traditional tools like Selenium and Puppeteer (Playwright Documentation). According to recent benchmarks, Playwright demonstrates up to 40% faster execution times compared to Selenium, while providing more reliable wait mechanisms and better cross-browser compatibility.

The framework's modern architecture and sophisticated API make it particularly well-suited for handling dynamic content, complex JavaScript-heavy applications, and single-page applications (SPAs). With support for multiple browser engines including Chromium, Firefox, and WebKit, Playwright offers unparalleled flexibility in web scraping scenarios (Microsoft .NET Blog).

This guide will walk through the essential components of implementing web scraping with Playwright in C#, from initial setup to advanced techniques and performance optimization strategies. Whether you're building a simple data extraction tool or a complex web automation system, this comprehensive implementation guide will provide the knowledge and best practices necessary for successful deployment.

Web Scraping with Playwright Java: A Runnable Maven Example

· 9 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Web Scraping with Playwright Java: A Runnable Maven Example

Correction (2026-09-30)

The earlier version contained disconnected Maven fragments, a subclass accessing a private field, an undefined robots helper, and an incorrect retry helper. Those were source-inspection findings, not compiler results from this experiment. This refresh replaces them with a tested project and removes unsupported hardware and performance claims.

A Java scraper needs to know when a page's data is complete, what a valid record looks like, and whether an empty result means success or failure. This walkthrough runs Playwright against an owned catalog whose products appear after JavaScript executes. It exports validated JSON and checks failure outcomes without contacting a customer site.

The complete Maven project includes the entry point, fixture server, scraper, build configuration and tests. Its captured run passed all six controlled scenarios. That is evidence about this fixture, not a success rate for arbitrary websites.

Proxy Rotation Implementation in Playwright

· 9 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Proxy Rotation Implementation in Playwright

This comprehensive guide explores the intricate details of proxy rotation implementation, drawing from extensive research and industry best practices. Proper proxy rotation can significantly reduce detection rates and improve scraping success rates by up to 85%. The implementation of proxy rotation in Playwright involves multiple sophisticated approaches, from dynamic pool management to geolocation-based rotation strategies. The key to successful proxy rotation lies in maintaining a balance between performance, reliability, and anonymity. This research delves into various implementation methods, best practices, and optimization techniques that enable developers to create robust proxy rotation systems within the Playwright framework. The guide addresses critical aspects such as authentication, monitoring, load balancing, and error handling, providing practical solutions for common challenges faced in proxy rotation implementation.

Playwright CAPTCHA: Tested Libraries and 1,200 Provider Requests

· 14 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Playwright CAPTCHA: Tested Libraries and 1,200 Provider Requests

Updated 2026-09-27

Clarified ScrapingAnt's role in avoiding risk-triggered CAPTCHAs and its limit with mandatory challenges. The paid-provider results and open-source observations remain from September 23; no experiments were rerun for this update.

Updated 2026-09-23

Replaced the old mixed-framework examples, invented solver endpoint and unsupported bypass claims with tested integrations and a reproducible evidence packet. The comparison contains 100 requests per provider/CAPTCHA pair, across six cases and two funded services. Playwright has no built-in stealth mode, and a returned CAPTCHA token is not proof that a protected submission succeeded.

If a CAPTCHA stops your Playwright script, first decide what you need to test. For your own application's automated tests, use provider test keys and verify the acceptance and rejection paths. For a live integration, record both the solver's response and the target server's decision. Clicking a checkbox, receiving HTTP 200, or obtaining a token is not enough.

This guide compares five library approaches and shows how to run the tested examples. The paid comparison contains 1,200 provider requests, including the original 120 observations and 1,080 additional requests. All paid failures remain in the results. The separate introductory four-task experiment is excluded from that denominator.

How to Scrape Google Images

· 13 min read
Satyam Tripathi
Satyam is a Python developer with a strong focus on automation and web scraping. He love writing and sharing his knowledge through blogs.

How to Scrape Google Images

Google Images is a major source of visual content on the web, and scraping these images can be very useful for research, image processing, creating datasets for machine learning, and more. However, due to Google's complex DOM structure and the dynamic nature of search results, accurately extracting images can be quite challenging.

Detecting Vanilla Playwright - An In-Depth Analysis

· 14 min read
Oleg Kulyk
Co-Founder @ ScrapingAnt

Detecting Vanilla Playwright - An In-Depth Analysis

In the rapidly evolving landscape of web and API testing, Playwright has established itself as a formidable tool for developers seeking robust and reliable testing solutions.

At the heart of mastering Playwright lies the concept of its "vanilla" state, which refers to the default configuration settings that are automatically applied when a new Playwright project is initialized. Understanding this vanilla state is crucial for developers as it provides a foundational setup that ensures consistency and scalability across different testing scenarios.

The default configuration includes essential elements such as browser launch options, test runner setup, and predefined environment variables, all of which contribute to a streamlined testing process. However, as with any automated tool, the use of Playwright in its vanilla state can be subject to detection by sophisticated anti-bot measures employed by websites.

Techniques such as browser fingerprinting, network traffic analysis, and JavaScript execution monitoring are commonly used to identify automated browsing activities. To counteract these detection methods, developers can employ various strategies to enhance the stealthiness of their Playwright scripts, including the use of custom user-agent strings, proxy servers, and stealth plugins.

This research delves into the intricacies of detecting and mitigating the vanilla state of Playwright, providing insights into best practices and advanced techniques to optimize its use in web and API testing.

How to Scrape Google Trends Data using Python

· 13 min read
Satyam Tripathi
Satyam is a Python developer with a strong focus on automation and web scraping. He love writing and sharing his knowledge through blogs.

How to Scrape Google Trends Data using Python

Google Trends tracks the popularity of search topics over time by collecting data from billions of searches. It's a valuable tool for analyzing trends, behaviors, and public interest. However, scraping Google Trends data can be challenging due to dynamic content and a complex DOM structure.