Scrape a Dynamic Website with Python

The Selenium and Playwright examples were re-run with Selenium 4.49, Playwright 1.62 and Python 3.12, and their output below is copied from that run. The Selenium example was rewritten because webdriver.Chrome() no longer accepts the executable_path argument used in the 2021 version. The Pyppeteer section was removed because the library is unmaintained. A second fixture was added for content that arrives after a delay. The ScrapingAnt API example was updated to the same fixtures but was not executed for this update; no API output is shown as measured. Code, fixtures and captured output: scrapingant-examples/examples/scrape-dynamic-website-with-python.
You open a page in the browser and the data is there. You fetch the same URL with requests, parse it with BeautifulSoup, and the field is empty or shows placeholder text. That is the symptom of a dynamic website: the HTML the server sends is not the HTML you see, because JavaScript changes the page after it loads. This tutorial shows how to confirm that diagnosis on a small fixture and how to get the rendered content with Selenium, Playwright, or the ScrapingAnt API, including the case where the content shows up only after a delay.
Video Tutorial
The video walks through the 2021 version of this article. The ideas are the same; the Selenium code below is the current one.
What is a dynamic website?
A dynamic website updates or loads content after the initial HTML arrives. The browser receives a basic HTML document plus JavaScript, and the JavaScript then fills in or replaces content, usually by calling an API (AJAX) or by rendering the whole page client-side (Single-Page Application).
A static website ships all of its content in the first response. example.com is one:
To see the difference without any network request, here is the smallest dynamic page: a <div> whose text is replaced by JavaScript as soon as the DOM is ready.
<html>
<head>
    <title>Dynamic Web Page Example</title>
    <script>
        window.addEventListener("DOMContentLoaded", function() {
            document.getElementById("test").innerHTML = "I ❤️ ScrapingAnt"
        }, false);
    </script>
</head>
<body>
    <div id="test">Web Scraping is hard</div>
</body>
</html>
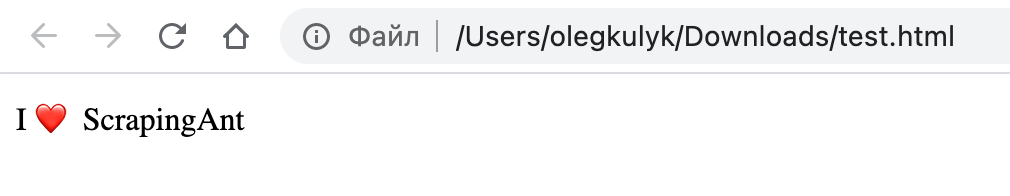
The file contains the text Web Scraping is hard. A browser shows I ❤️ ScrapingAnt:
There is a second fixture that does the same replacement 1500 ms after load and then appends a <div id="loaded"> marker. It simulates content that arrives from an API call, and it is where scrapers that already use a browser still go wrong.
<html>
<head>
    <title>Delayed Dynamic Web Page Example</title>
    <script>
        window.addEventListener("DOMContentLoaded", function() {
            setTimeout(function() {
                document.getElementById("test").innerHTML = "I ❤️ ScrapingAnt (after 1500 ms)";
                var done = document.createElement("div");
                done.id = "loaded";
                done.textContent = "loaded";
                document.body.appendChild(done);
            }, 1500);
        }, false);
    </script>
</head>
<body>
    <div id="test">Web Scraping is hard</div>
</body>
</html>
Running the examples
Every snippet below is a file in the examples repository, with the fixtures next to it. To run them as they were tested:
git clone https://github.com/ScrapingAnt/scrapingant-examples.git
cd scrapingant-examples/examples/scrape-dynamic-website-with-python
python3.12 -m venv .venv && . .venv/bin/activate
pip install -r requirements.txt        # pinned: selenium 4.49.0, playwright 1.62.0, beautifulsoup4 4.15.0, requests 2.34.2, scrapingant-client 2.1.0
python -m playwright install chromium
./run.sh                               # runs 01..03; runs 04 only if SCRAPINGANT_API_KEY is set
The Selenium step needs Google Chrome installed. The snippets in the article open the fixtures by relative path from that directory; the repository scripts do the same through a small helper that resolves the paths.
Step 1: confirm the diagnosis with a plain parser
BeautifulSoup parses HTML; it does not run JavaScript. Parsing both fixtures with it shows exactly what a requests-based scraper sees:
from bs4 import BeautifulSoup
from pathlib import Path

for name in ("dynamic-domcontentloaded", "dynamic-delayed"):
    html = Path(f"fixtures/{name}.html").read_text(encoding="utf-8")
    soup = BeautifulSoup(html, "html.parser")
    print(f"{name}: {soup.find(id='test').get_text()}")
Output:
domcontentloaded: Web Scraping is hard
delayed: Web Scraping is hard
If your scraper's output matches the raw HTML but not the browser, this is your situation. The parser is fine; nothing executed the JavaScript. The rest of the article is about who executes it: a browser you control (Selenium, Playwright) or a browser in the cloud (the API).
Selenium 4: headless Chrome without a manual driver download
Selenium drives a real browser through a driver binary. Since Selenium 4.6, Selenium Manager downloads a chromedriver that matches your installed Chrome, so the 2021 steps of downloading the driver by hand are gone. The executable_path argument is deprecated in Selenium 4 in favour of a Service object (upgrade guide), and in 4.49.0 webdriver.Chrome() does not accept it at all; its constructor takes options, service and keep_alive. If you need a specific driver binary, pass service=Service(executable_path=...).
import selenium
from pathlib import Path

from bs4 import BeautifulSoup
from selenium import webdriver
from selenium.webdriver.chrome.options import Options
from selenium.webdriver.common.by import By
from selenium.webdriver.support import expected_conditions as EC
from selenium.webdriver.support.ui import WebDriverWait

opts = Options()
opts.add_argument("--headless=new")
driver = webdriver.Chrome(options=opts)  # Selenium Manager resolves chromedriver
print(f"selenium {selenium.__version__}, chrome {driver.capabilities['browserVersion']}")

driver.get(Path("fixtures/dynamic-domcontentloaded.html").resolve().as_uri())
soup = BeautifulSoup(driver.page_source, "html.parser")
print(f"domcontentloaded: {soup.find(id='test').get_text()}")

driver.get(Path("fixtures/dynamic-delayed.html").resolve().as_uri())
soup = BeautifulSoup(driver.page_source, "html.parser")
print(f"delayed, read immediately: {soup.find(id='test').get_text()}")

WebDriverWait(driver, 10).until(EC.presence_of_element_located((By.ID, "loaded")))
soup = BeautifulSoup(driver.page_source, "html.parser")
print(f"delayed, after waiting for #loaded: {soup.find(id='test').get_text()}")

driver.quit()
Captured output:
selenium 4.49.0, chrome 152.0.7977.84
domcontentloaded: I ❤️ ScrapingAnt
delayed, read immediately: Web Scraping is hard
delayed, after waiting for #loaded: I ❤️ ScrapingAnt (after 1500 ms)
The third line is the important one. driver.get() returns when the page has loaded, and for the delayed fixture that is before the JavaScript has replaced the text. A browser alone does not fix a dynamic page; you also have to wait for the thing you need. WebDriverWait with an expected condition is the right tool; a fixed time.sleep() is a guess that is either too short or wastes time.
If the element never appears, until() raises selenium.common.exceptions.TimeoutException after the 10 seconds. Catch it, save driver.page_source to a file, and look at what the page actually contained: usually the selector is wrong, the content is inside an iframe, or the site returned a block page instead of the real one.
Selenium's strengths are browser choice and a large ecosystem. Its cost is a full browser per process and a fair amount of boilerplate.
Playwright: the same job with a smaller API
Playwright installs its own browser builds (Chromium, Firefox, WebKit) and has an official Python package with sync and async APIs. Waiting for elements is built in.
from pathlib import Path

from bs4 import BeautifulSoup
from playwright.sync_api import sync_playwright

with sync_playwright() as p:
    browser = p.chromium.launch()
    print(f"playwright chromium {browser.version}")
    page = browser.new_page()

    page.goto(Path("fixtures/dynamic-domcontentloaded.html").resolve().as_uri())
    soup = BeautifulSoup(page.content(), "html.parser")
    print(f"domcontentloaded: {soup.find(id='test').get_text()}")

    page.goto(Path("fixtures/dynamic-delayed.html").resolve().as_uri())
    soup = BeautifulSoup(page.content(), "html.parser")
    print(f"delayed, read immediately: {soup.find(id='test').get_text()}")

    page.wait_for_selector("#loaded", timeout=10_000)
    soup = BeautifulSoup(page.content(), "html.parser")
    print(f"delayed, after waiting for #loaded: {soup.find(id='test').get_text()}")

    browser.close()
Captured output:
playwright chromium 151.0.7922.34
domcontentloaded: I ❤️ ScrapingAnt
delayed, read immediately: Web Scraping is hard
delayed, after waiting for #loaded: I ❤️ ScrapingAnt (after 1500 ms)
Same behaviour, same lesson: page.content() right after goto() is too early for delayed content, and wait_for_selector fixes it. On timeout it raises playwright.sync_api.TimeoutError; handle it the same way as above, and page.screenshot(path="debug.png") is a quick way to see what the browser had at that moment. If you are starting a new project and only need Chromium, Playwright is the less fiddly of the two.
Both local approaches are free and sufficient when you control the pages, or when you scrape a small number of pages at a polite rate. They stop being sufficient when you need many browsers running in parallel, or when keeping browsers and drivers patched becomes a job of its own.
ScrapingAnt API: rendering in the cloud
The ScrapingAnt API runs the headless browser on its side; you make one HTTP request per page and get the rendered HTML back. The example fetches the public copies of the same two fixtures, because the API has to reach them over the internet. This example was not executed for this update, so no output is shown; the parameters are taken from the request format documentation.
import os

import requests
from bs4 import BeautifulSoup

API_KEY = os.environ["SCRAPINGANT_API_KEY"]
ENDPOINT = "https://api.scrapingant.com/v2/general"
BASE = "https://scrapingant.github.io/scrapingant-examples/fixtures/"


def fetch(url, **params):
    # The key goes in a header, not the query string, so it does not end up in URL logs.
    r = requests.get(ENDPOINT, params={"url": url, **params}, headers={"x-api-key": API_KEY}, timeout=120)
    r.raise_for_status()
    return r.text, r.headers.get("Ant-credits-cost", "?")


# 1. Default request: headless browser with JavaScript rendering.
html, cost = fetch(BASE + "dynamic-domcontentloaded.html")
print(f"domcontentloaded (browser=true): {BeautifulSoup(html, 'html.parser').find(id='test').get_text()}  [credits: {cost}]")

# 2. Same page without a browser (1 credit instead of 10): JavaScript never runs.
html, cost = fetch(BASE + "dynamic-domcontentloaded.html", browser="false")
print(f"domcontentloaded (browser=false): {BeautifulSoup(html, 'html.parser').find(id='test').get_text()}  [credits: {cost}]")

# 3. Delayed content: tell the API which element to wait for before returning.
html, cost = fetch(BASE + "dynamic-delayed.html", wait_for_selector="#loaded")
print(f"delayed (wait_for_selector=#loaded): {BeautifulSoup(html, 'html.parser').find(id='test').get_text()}  [credits: {cost}]")
Three things to notice:
browser=falseturns rendering off and returns the raw HTML, so for a dynamic page it gives you the same result asrequests. Use it for static pages. Per the credit cost table, a request without a browser through a datacenter proxy to a non-Google domain costs 1 credit, and a JavaScript-rendered request through a datacenter proxy costs 10, so this is one tenth of the price.wait_for_selectoris the API's equivalent ofWebDriverWaitandpage.wait_for_selector: the API waits for that element before it returns the page.- Every response carries an
Ant-credits-costheader with the credits that request consumed, so you can measure cost per page instead of estimating it (custom headers).raise_for_status()turns a 4xx or 5xx from the API into an exception; the response body explains why (for example a wrong key or a page that could not be loaded).
The official scrapingant-client wraps the same endpoint with the same parameter names and sends the key as a header for you:
from bs4 import BeautifulSoup
from scrapingant_client import ScrapingAntClient

client = ScrapingAntClient(token="<YOUR-SCRAPINGANT-API-KEY>")
result = client.general_request(
    "https://scrapingant.github.io/scrapingant-examples/fixtures/dynamic-delayed.html",
    wait_for_selector="#loaded",
)
print(BeautifulSoup(result.content, "html.parser").find(id="test").get_text())
The client's response object exposes content, text, status_code and cookies but not headers, so use requests directly when you want the credit cost.
Which one should you use?
| Situation | Use |
|---|---|
| Your own pages, or a few pages from one site | Playwright (or Selenium if you need a specific browser) |
| Content appears after a delay | Any of the three, always with an explicit wait for the element you need |
| Static page (no JavaScript needed) | requests; or the API with browser=false if you already use it |
| Many pages in parallel, no time to maintain browsers | ScrapingAnt API with rendering |
The first check is always the parser test from Step 1. If the raw HTML already contains your data, you do not need a browser at all, local or remote.
Limitations
- The fixtures are two synthetic pages. They show the mechanism (JavaScript replaces content, once immediately and once after a delay), not real-site behaviour such as anti-bot checks, login walls or network latency.
- The API example was not run for this update. Its credit costs are quoted from the documentation, not measured with the
Ant-credits-costheader. - Version numbers are those tested on 2026-09-14; newer Selenium or Playwright releases may change defaults.
Summary
Dynamic pages fail plain parsers because nobody ran the JavaScript. Selenium 4 and Playwright run it locally; the ScrapingAnt API runs it in the cloud. In all three, reading the page immediately after load is not enough for content that arrives later; wait for the element you need. Further reading:
- Web browser automation with Python and Playwright
- Top 5 Popular Python Libraries for Web Scraping
- Selenium documentation
- Playwright for Python
- ScrapingAnt documentation
Selenium and Playwright examples tested on 2026-09-14 with Python 3.12.10, Selenium 4.49.0 (Chrome 152), Playwright 1.62.0 (Chromium 151) and beautifulsoup4 4.15.0; the API example was not executed. Code, fixtures and captured output: scrapingant-examples, tag scrape-dynamic-website-with-python/2026-09-14.
This article was drafted with AI assistance from a tested evidence packet and reviewed by the named author, who is responsible for the code, measurements and corrections.