Web Scraping with Playwright Series Part 1 - Getting Started

Added a section that fetches the same page through the ScrapingAnt API, run once against the live API on 2026-10-26. The rest of the article was not re-tested in this update.
Introducing the 4-Part Series on Web Scraping with Playwright! This comprehensive series will delve into web scraping using Playwright, a powerful and versatile tool for automating browser interactions.
By the end of this series, you'll have a solid understanding of web scraping with Playwright. You'll be able to build robust scrapers that can handle dynamic content, efficiently store data, and navigate through anti-scraping mechanisms.
In Part 1, you'll learn about the basics of Playwright, why it's useful, how to set up the environment, how to launch the browser using Playwright, and how to take screenshots.
What is Playwright
Playwright is a free, open-source framework for browser testing and automation, developed by Microsoft and launched in 2020. It has become popular among programmers and web developers for its ease of use and powerful features.
Playwright allows developers to automate browser tasks across Chromium, Firefox, and WebKit using a single API. While its main API was originally written in Node.js, Playwright offers cross-language support, including Python, JavaScript, .NET, and Java. For this blog, however, we'll focus on using Python.
Playwright is also crucial for web scraping, especially for modern JavaScript-heavy websites where traditional HTML parsing tools like Beautiful Soup struggle. Its simplicity and powerful automation capabilities make it an ideal tool for web scraping and data mining.
Why Use Playwright
The playwright is particularly useful due to the following features:
- Auto-wait: The playwright waits for elements to become actionable before taking action. It also features a rich set of introspective events. This combination eliminates the need for artificial timeouts, the primary cause of flaky tests.
- Web-first assertions: Playwright assertions are created specifically for the dynamic web. They automatically retry checks until the expected conditions are met, ensuring your tests are robust.
- Browser contexts: The playwright creates a separate browser context (like a fresh browser profile) for each test. This delivers full test isolation with zero overhead.
- Tracing: Playwright allows you to configure test retries, and capture detailed execution traces, videos, and screenshots.
Setting up your environment
Before scraping websites, let's set up our system's Python environment for Playwright by following a few straightforward steps:
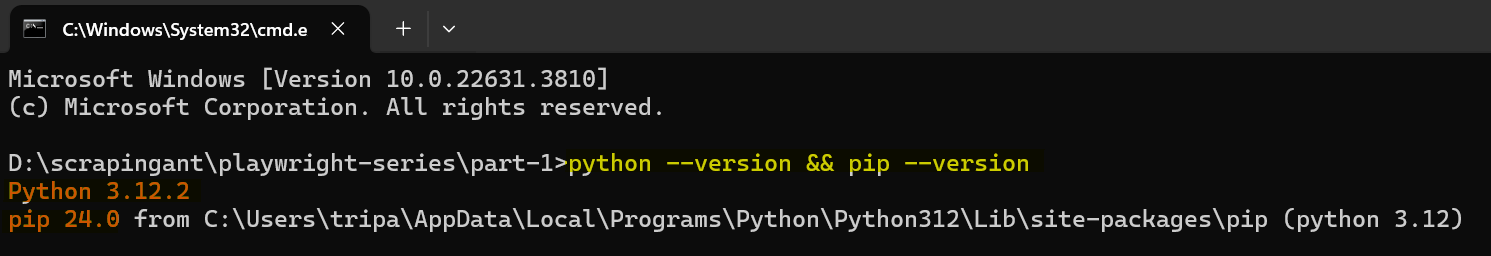
Step 1: Make sure you have Python and Pip installed on your system.
python --version && pip --version
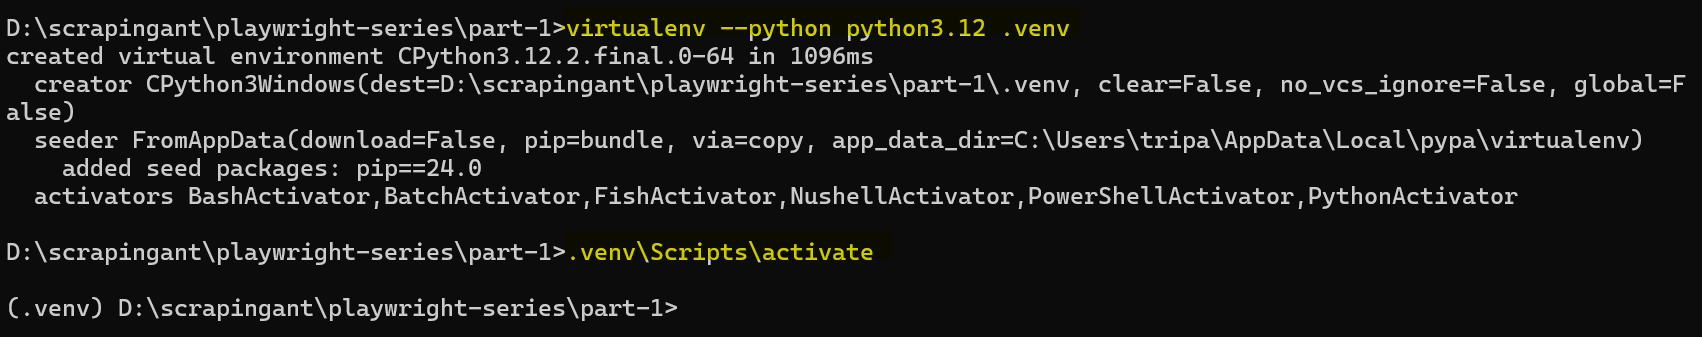
Step 2: Optionally, create a Python virtual environment (using Virtualenv).
virtualenv --python python3.12 .venv
.venv\Scripts\activate
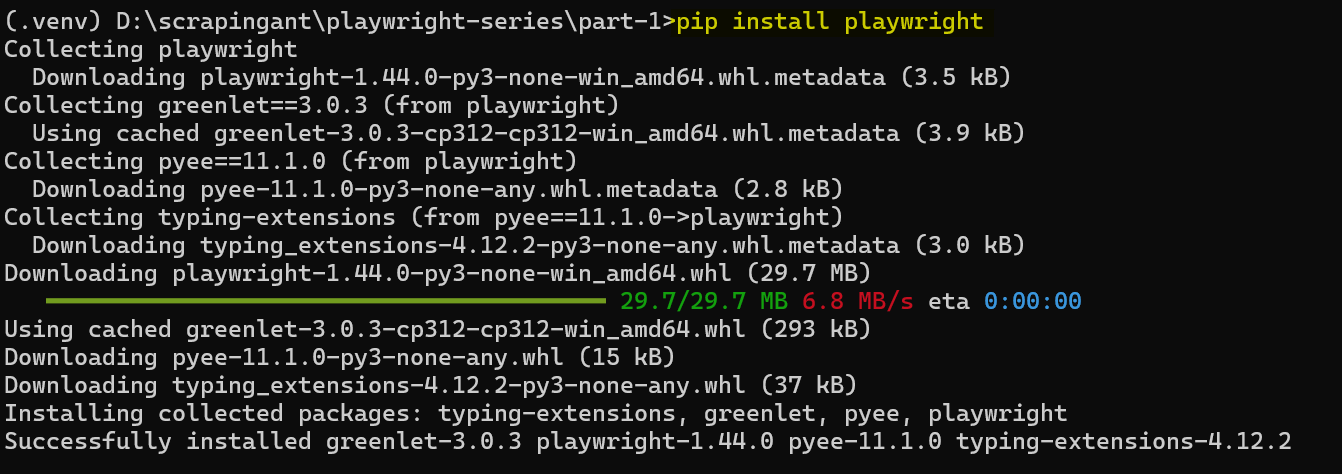
Step 3: Install the PyPI packages that we will use in this blog.
pip install playwright==1.44.0
Step 4: Run the following command to install the necessary browser binaries.
playwright install
This will install the latest versions of Chromium, Firefox, and WebKit. You can use any of these browsers in your code, but we'll use Chromium for this tutorial.
Step 5: Create a Python file (e.g., main.py) where we will write all our web scraping code. My project directory looks like this:
D:\scrapingant\playwright-series\part-1
│
├── .venv
│   ├── Scripts
│   ├── ... (other virtual environment folders)
│
├── main.py (or any other Python files you create)
Launching Playwright
Playwright for Python offers both synchronous and asynchronous APIs. We'll start with a simple synchronous script to open a browser, navigate to a URL, and extract the website's title.
from playwright.sync_api import Playwright, sync_playwright

def run(playwright: Playwright, url: str):
    # Launch Chromium in non-headless mode (visible UI)
    browser = playwright.chromium.launch(headless=False)

    # Open a new browser page with specified dimensions
    page = browser.new_page(viewport={"width": 1600, "height": 900})

    # Navigate to the given URL
    page.goto(url)

    # Get the page title
    title = page.title()

    # Close the browser
    browser.close()

    # Return the URL and title as a dictionary
    return {"url": url, "title": title}

def main():
    # Use sync_playwright to manage the Playwright instance
    with sync_playwright() as playwright:
        result = run(playwright, url="https://scrapingant.com/")
        print(result)

if __name__ == "__main__":
    main()
The result is:
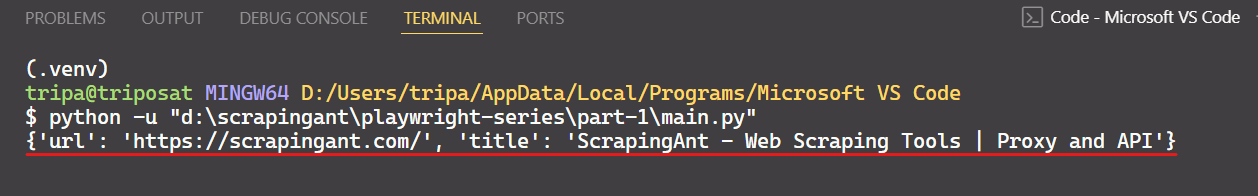
Now let's see Playwright's async API and Asyncio in action. Asynchronous programming is particularly useful for I/O-bound tasks like web scraping. It allows us to perform other work concurrently, like waiting for HTTP responses, storing data in a file, or interacting with databases – all without blocking the main thread.
We will convert our initial script into an asynchronous version using Playwright's async API and Asyncio, a standard Python library for writing concurrent code using the async/await syntax.
import asyncio
from playwright.async_api import Playwright, async_playwright

async def run(playwright: Playwright, url: str):
    # Launch Chromium in non-headless mode (visible UI)
    browser = await playwright.chromium.launch(headless=False)

    # Open a new browser page with specified dimensions
    page = await browser.new_page(viewport={"width": 1600, "height": 900})

    # Navigate to the given URL
    await page.goto(url)

    # Get the page title
    title = await page.title()

    # Close the browser
    await browser.close()

    # Return the URL and title as a dictionary
    return {"url": url, "title": title}

async def main():
    # Use async_playwright to manage the Playwright instance
    async with async_playwright() as playwright:
        result = await run(playwright, url="https://scrapingant.com/")
        print(result)

if __name__ == "__main__":
    asyncio.run(main())
By leveraging asynchronous programming, we've ensured the script's performance remains optimal while preparing it for intricate and resource-intensive web scraping operations.
ScrapingAnt API
The same page without running a browser
When you need the rendered page rather than a browser you drive, one ScrapingAnt API call loads it in headless Chrome behind rotating proxies: no browser binaries to install, no Chromium fleet to scale and no proxy pool to maintain. Pick any proxy_country at no extra charge; requests the API answers with a non-200 status are not charged, and there is a free plan to start.
import requests
from bs4 import BeautifulSoup

response = requests.get(
    "https://api.scrapingant.com/v2/general",
    params={"url": "https://scrapingant.com/", "x-api-key": "YOUR_API_KEY"},  # rendered in headless Chrome by default
    timeout=60,
)
print(response.status_code, response.headers["Ant-Page-Status-Code"])
print(BeautifulSoup(response.text, "html.parser").title.get_text(strip=True))
200 200
ScrapingAnt — Web Scraping API, Proxies, and AI Extraction in One Stack
The second number is Ant-Page-Status-Code, the target's own status. Run on 2026-10-26 with requests 2.34.2 and beautifulsoup4 4.15.0.
Taking Screenshots with Playwright
One of Playwright's key functionalities is screenshot-taking. Automated screenshotting has many commercial use cases, most notably in web scraping and testing.
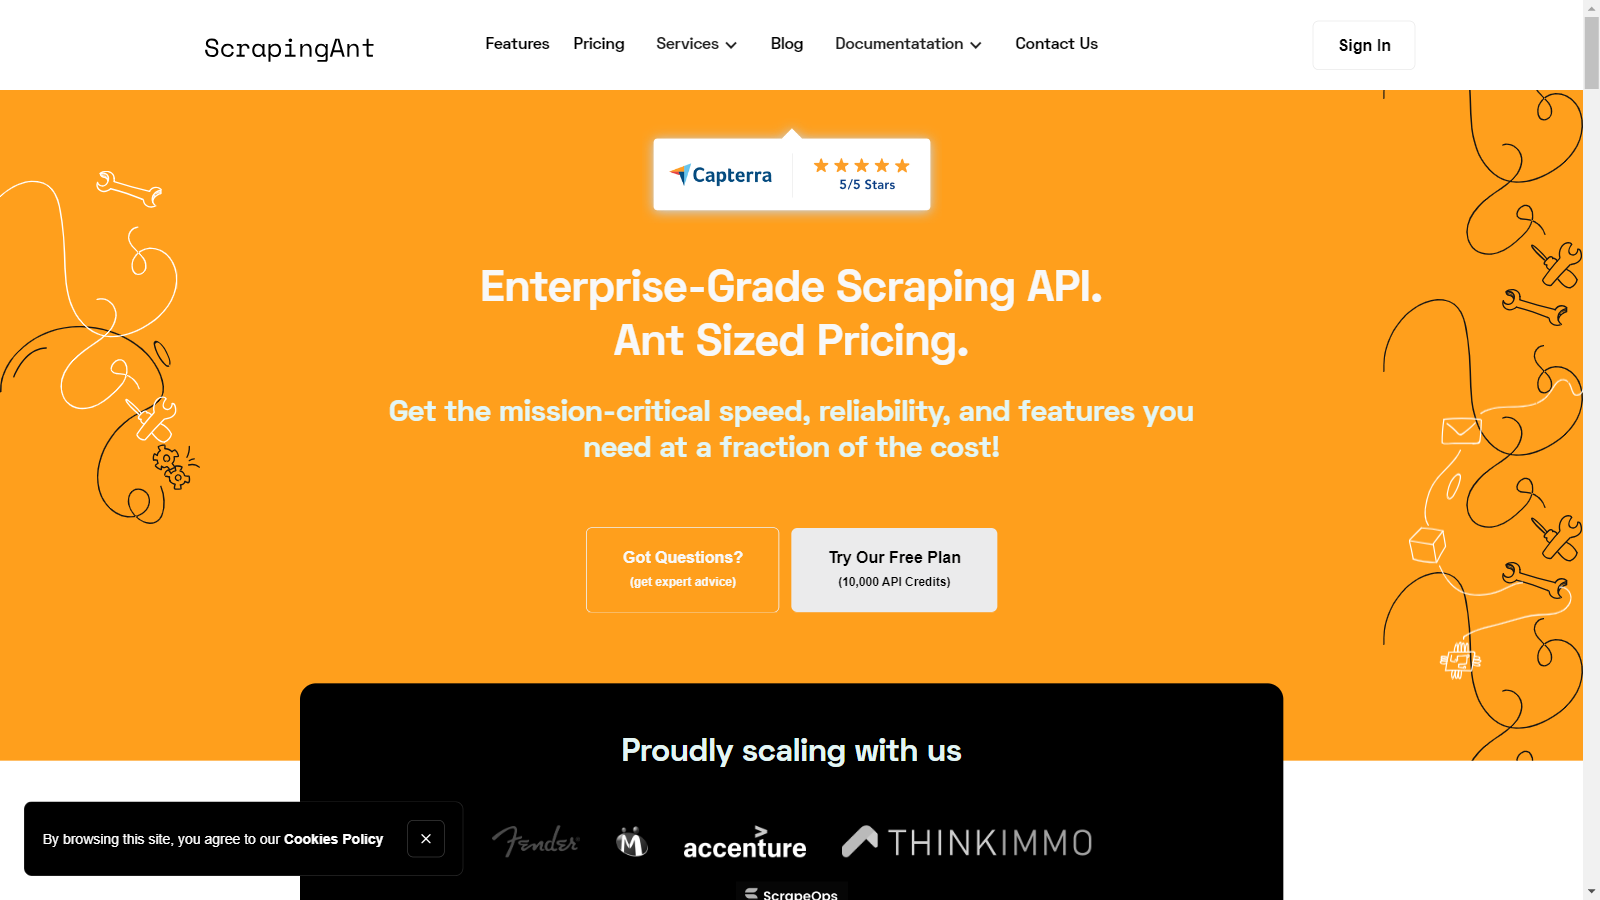
Capturing the visible portion of the screen is the easiest way to take a screenshot in Playwright. To achieve this, navigate to the desired website and then use the screenshot method on the page object.
import asyncio
from playwright.async_api import Playwright, async_playwright

async def run(playwright: Playwright, url: str):
    # Launch Chromium in non-headless mode (visible UI)
    browser = await playwright.chromium.launch(headless=False)

    # Open a new browser page with specified dimensions
    page = await browser.new_page(viewport={"width": 1600, "height": 900})

    # Navigate to the given URL
    await page.goto(url)

    # Add a sleep to ensure the page is fully loaded
    await asyncio.sleep(3)  # Wait for 3 seconds

    # Take a screenshot
    await page.screenshot(path="visible_part.png")

    # Close the browser
    await browser.close()

async def main():
    # Use async_playwright to manage the Playwright instance
    async with async_playwright() as playwright:
        await run(playwright, url="https://scrapingant.com/")

if __name__ == "__main__":
    asyncio.run(main())
Great! The above code captures a screenshot of the visible part of the target page, and you'll find the output in your project directory.
The result is:
Next, let's increase your coverage to capture the entire web page. Playwright lets you take a screenshot, including elements that require scrolling. For example, here's a screenshot of the target page:
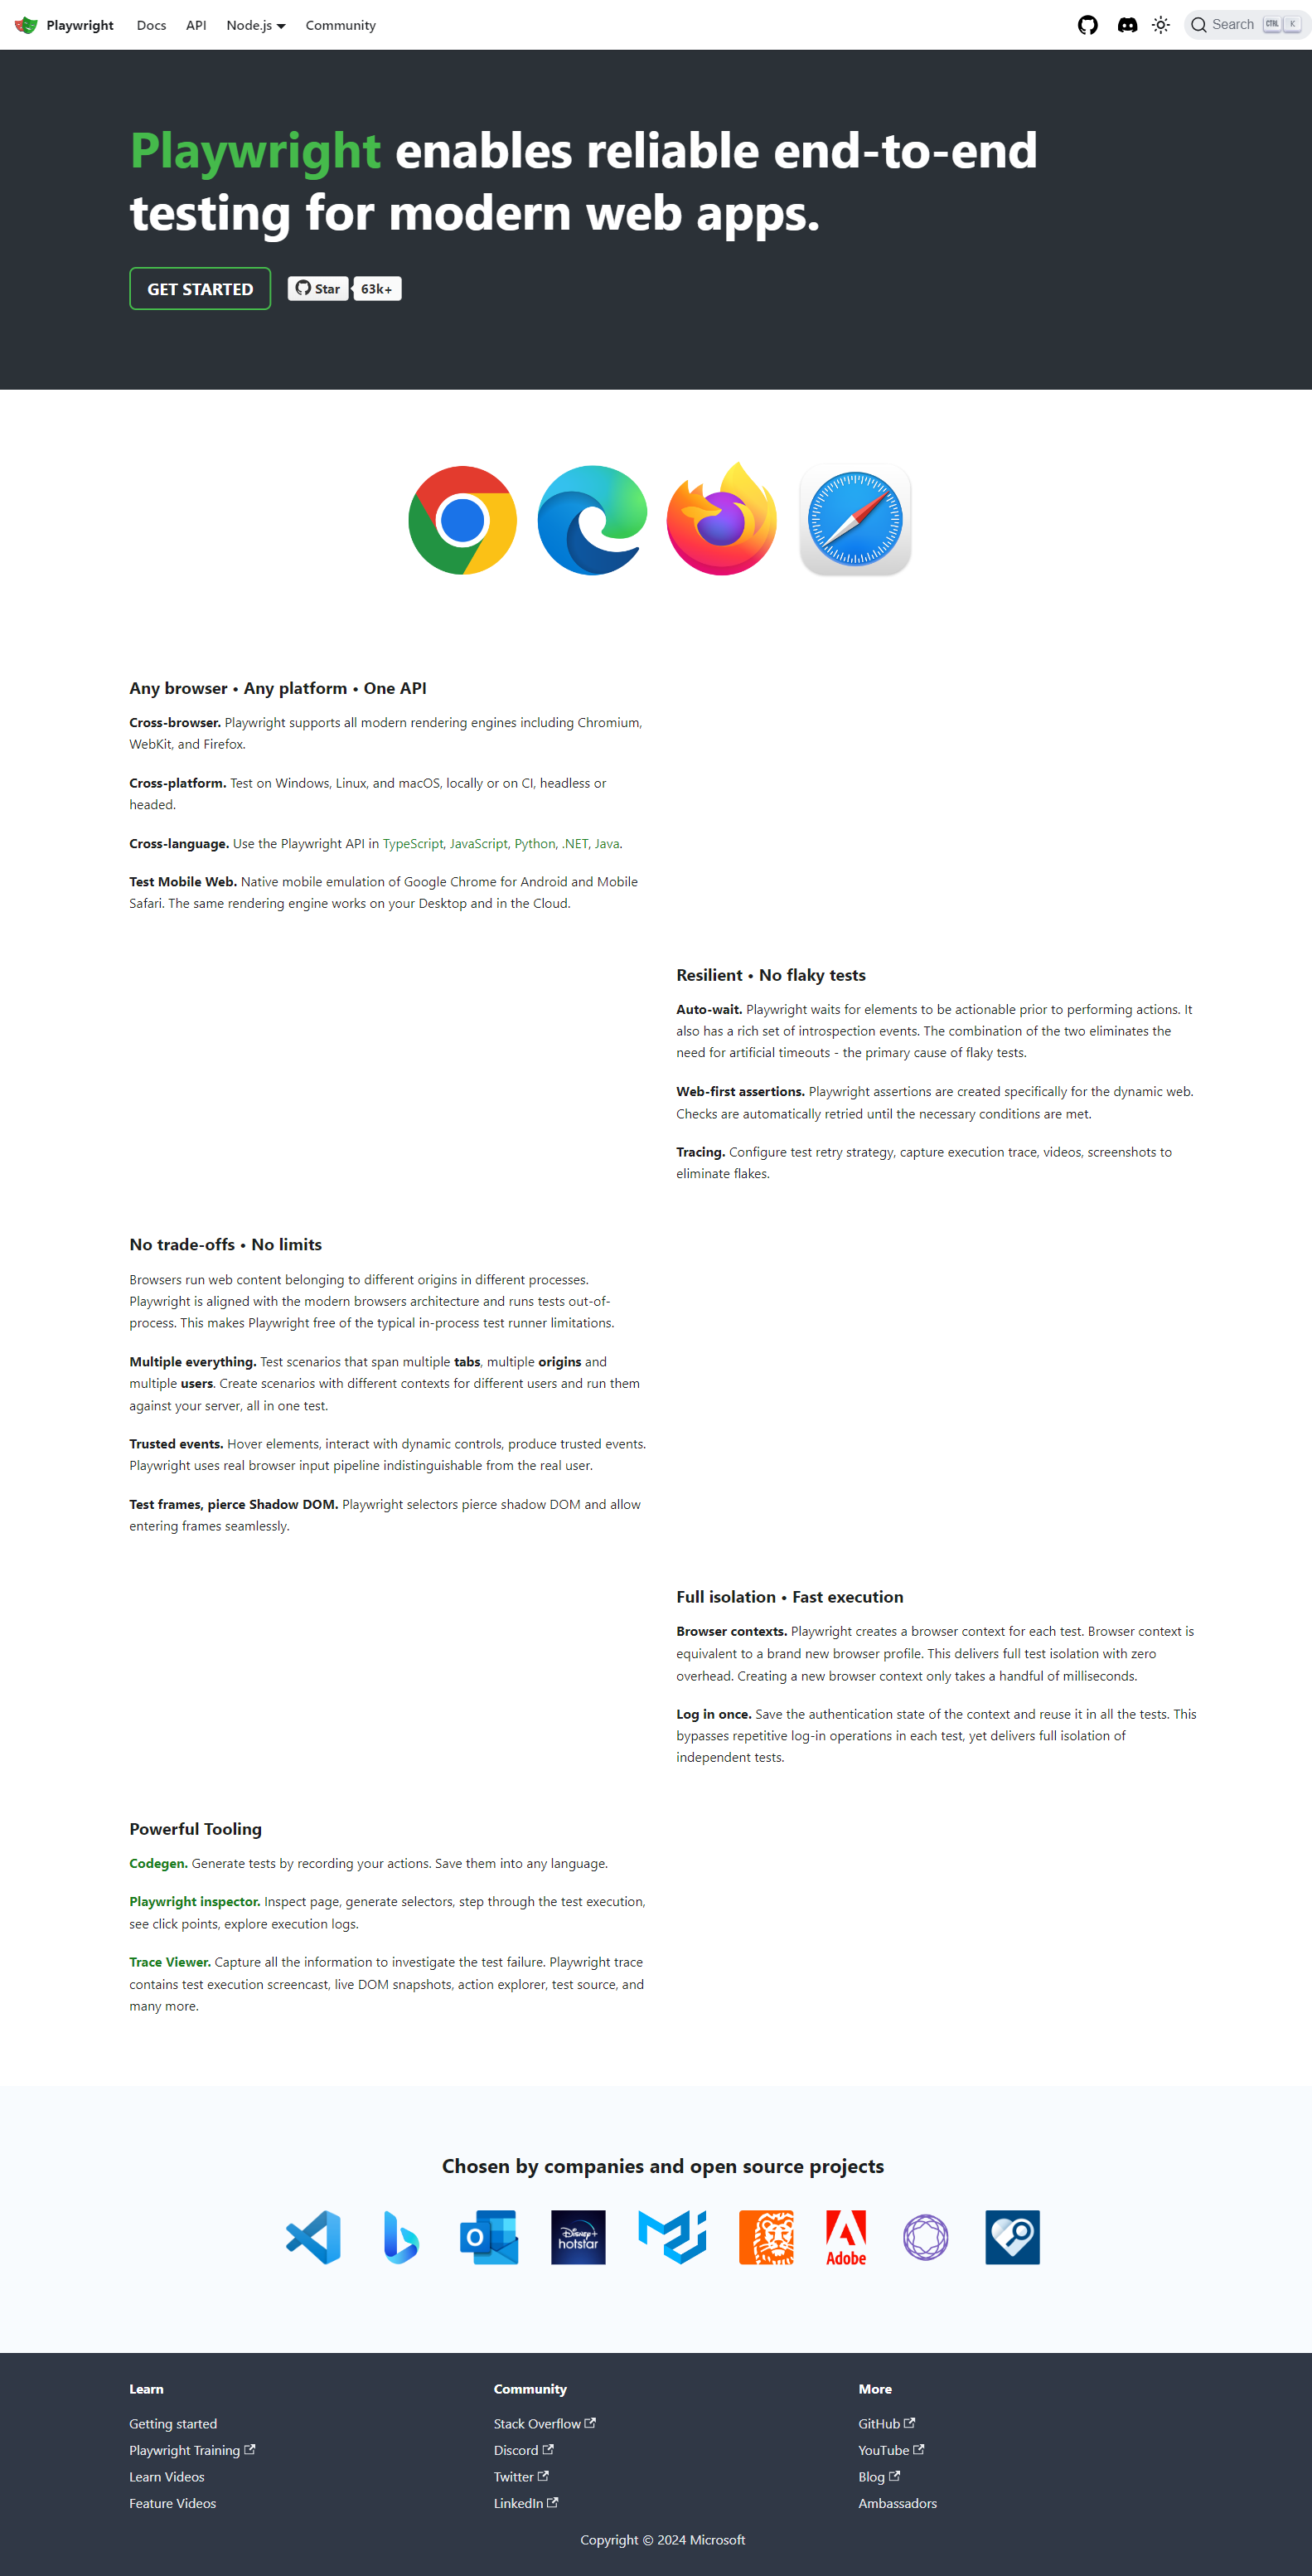
To get the same result, you need to add the full_page parameter to the screenshot method and set its value to True.
import asyncio
from playwright.async_api import Playwright, async_playwright

async def run(playwright: Playwright, url: str):
    # Launch Chromium in non-headless mode (visible UI)
    browser = await playwright.chromium.launch(headless=False)

    # Open a new browser page with specified dimensions
    page = await browser.new_page(viewport={"width": 1600, "height": 900})

    # Navigate to the given URL
    await page.goto(url)

    # Add a sleep to ensure the page is fully loaded
    await asyncio.sleep(3)  # Wait for 3 seconds

    # Take a screenshot
    await page.screenshot(path='full_page.png', full_page=True)

    # Close the browser
    await browser.close()

async def main():
    # Use async_playwright to manage the Playwright instance
    async with async_playwright() as playwright:
        await run(playwright, url="https://playwright.dev/")

if __name__ == "__main__":
    asyncio.run(main())
Yes, it's so simple!
Next step
In Part 2, we'll build a scraper from scratch, diving into advanced techniques like handling dynamic scrolling, network events, and blocking images and resources.