BeautifulSoup Cheat Sheet (bs4 4.15): Tested Snippets, Parsers, Traps

Rewritten as a tested cheat sheet. Every snippet below was run by the example package against one fixture page on beautifulsoup4 4.15.0, and the output is copied from that run. The 2024 version had no captured output (only inline # Output: comments), used the text= argument that has warned since 4.11, passed from_encoding to a str (ignored), and called pd.read_html with a string that pandas 3 now treats as a filename; all corrected. New: parsers compared on broken markup, a CPU-time table with min/median/max columns and a note on how much such timings move under load, the 4.13–4.15 deprecations captured with a type-checked example, and the errors you will actually see.
pip install beautifulsoup4 lxml # html5lib, requests and pandas only for the sections that use them
from bs4 import BeautifulSoup
with open("fixtures/page.html", encoding="utf-8") as f:
    PAGE = f.read()

soup = BeautifulSoup(PAGE, "html.parser")                 # from a str
print(soup.title.string, "|", soup.h1.get_text(" ", strip=True))
Ant Supply — catalogue | Products (3)
That is the whole idea: parse, find, read. The sheet below is the rest of it, every line run against the same fixture page (a small catalogue with a nav, three product cards, a table, a comment and a script).
How the outputs were captured
The package (examples/beautifulsoup-cheatsheet) has one script per section; each prints directly, and the output blocks are copied from the recorded run. Lines that raise are run through a small helper, show(), that prints the exception's type and message instead of a traceback. The sections below share one set of imports (re, requests, pandas as pd, io.StringIO) and one soup parsed from the fixture, as the scripts do. Versions:
python: Python 3.12.11
beautifulsoup4 4.15.0
lxml 6.1.3
html5lib 1.1
soupsieve 2.9.2
requests 2.34.2
pandas 3.0.5
libxml2 2.14.6
1. Parse: strings, files, responses, encodings
soup = BeautifulSoup(PAGE, "html.parser")                 # from a str
print(soup.title.string, "|", soup.h1.get_text(" ", strip=True))
with open("fixtures/page.html", "rb") as f:               # from a file object (bytes: bs4 detects the encoding)
    soup = BeautifulSoup(f, "lxml")
print(soup.original_encoding, soup.title.string)

r = requests.get("https://scrapingant.github.io/scrapingant-examples/fixtures/dynamic-delayed.html", timeout=30)
soup = BeautifulSoup(r.content, "html.parser")            # bytes from a response; not r.text
print(r.status_code, soup.original_encoding, soup.title.string)

latin1 = "<p>Gr\u00fc\u00dfe aus M\u00fcnchen</p>".encode("latin-1")
print(BeautifulSoup(latin1, "html.parser").p.string)                                   # guessed: wrong or right by luck
print(BeautifulSoup(latin1, "html.parser", from_encoding="latin-1").p.string)         # told
Ant Supply — catalogue | Products (3)
utf-8 Ant Supply — catalogue
200 utf-8 Delayed Dynamic Web Page Example
Grüße aus München
Grüße aus München
Give the constructor bytes (r.content, a file opened "rb") and let it detect the encoding; original_encoding tells you what it decided. from_encoding overrides the guess and only makes sense for bytes; on a str it is ignored with a warning. And a filename is not markup:
show("from_encoding on a str", lambda: BeautifulSoup("<p>x</p>", "html.parser", from_encoding="latin-1").p.string)
show('BeautifulSoup("fixtures/page.html")  # a filename is not markup', lambda: BeautifulSoup("fixtures/page.html", "html.parser").get_text())
warning: UserWarning: You provided Unicode markup but also provided a value for from_encoding. Your from_encoding will be ignored.
from_encoding on a str: 'x'
warning: MarkupResemblesLocatorWarning: The input passed in on this line looks more like a filename than HTML or XML.
(The MarkupResemblesLocatorWarning goes on to tell you to open the file first; the package output has the full text.)
2. Parsers: the same broken fragment, three trees
html.parser ships with Python, lxml and html5lib are packages. They agree on well-formed pages and disagree on broken ones. The fragment <div class="card"><p>Unclosed paragraph<p>Second <b>bold <i>bold-italic</b> italic?</i></div><span>after through each:
--- html.parser
<div class="card"><p>Unclosed paragraph<p>Second <b>bold <i>bold-italic</i></b> italic?</p></p></div><span>after
</span>
--- lxml
<html><body><div class="card"><p>Unclosed paragraph</p><p>Second <b>bold <i>bold-italic</i></b> italic?</p></div><span>after
</span></body></html>
--- html5lib
<html><head></head><body><div class="card"><p>Unclosed paragraph</p><p>Second <b>bold <i>bold-italic</i></b><i> italic?</i></p></div><span>after
</span></body></html>
html.parser nests the second <p> inside the first and drops the stray </b>; lxml closes the first paragraph and wraps everything in html/body; html5lib does what a browser does, including re-opening <i> after the misnested </b>. So a selector like p:nth-of-type(2) finds different things per parser, which is the reason to name the parser explicitly and never rely on the default. bs4.diagnose.diagnose(markup) prints all three trees for any fragment (the package records it).
CPU time on a generated 3.1 MB page with 20,000 product cards, parsing and collecting every p.price, seven runs per case in separate processes:
file: generated/large.html, 3.1 MB, 20,000 products; task: parse and collect every p.price; CPU seconds over 7 runs, one subprocess per run
case                               min  median     max   count
BeautifulSoup html.parser         1.18    1.20    1.30   20000
BeautifulSoup lxml                0.89    0.90    0.91   20000
BeautifulSoup html5lib            2.33    2.35    2.40   20000
BeautifulSoup lxml + select       0.97    0.99    1.00   20000
lxml.html + xpath (no bs4)        0.08    0.08    0.08   20000
Reading it: in this run lxml is the fastest tree builder for BeautifulSoup, html.parser about a third slower, html5lib about 2.6× slower, and select costs about the same as find_all once the tree exists. Going through lxml.html directly, with XPath and no BeautifulSoup tree, is an order of magnitude faster than the fastest BeautifulSoup build (0.08 s against 0.89 s), which is the trade you make for BeautifulSoup's API. One caution the min/median/max columns exist for: earlier recordings made while other processes were running on the same machine spread the builder timings by up to 3.7× and reordered them, so run the package on a quiet machine before quoting a ranking of your own. Pick lxml by default, html5lib when the page is broken in ways that matter, html.parser when you cannot install anything.
3. Find
print(soup.find("h2"))                                            # first match, or None
print([a["href"] for a in soup.find_all("a")])                    # by tag name
print([t.name for t in soup.find_all(["h1", "h2"])])              # list of names
print(len(soup.find_all(True)))                                   # every tag
print([p.string for p in soup.find_all("p", class_="price")])     # class_ (class is a keyword)
print([d["data-sku"] for d in soup.find_all("div", attrs={"data-sku": True})])   # attrs dict; True = present
print([d["data-sku"] for d in soup.find_all("div", class_="featured")])          # matches one of several classes
print(soup.find("div", attrs={"data-sku": "A200"}).h2.a.string)
print([a.string for a in soup.find_all("a", href=re.compile(r"^/p/"))])          # regex on an attribute
print([p.string for p in soup.find_all("p", string=re.compile(r"stock"))])       # string= matches the text
print([li.string for li in soup.find_all("li", limit=2)])
print(len(soup.find_all("li")), len(soup.find("section").find_all("div", recursive=False)))
print([t.name for t in soup.find_all(lambda tag: tag.name == "p" and "in" in tag.get("class", []))])   # a function
show("soup.find('h9')", lambda: soup.find("h9"))
print(soup.find(id="top").name, soup.find(id="missing"))
<h2><a href="/p/a100">Ant Farm Deluxe</a></h2>
['/', '/catalogue', 'https://example.com/help', '/p/a100', '/p/a200', '/p/a300', 'mailto:hello@example.com']
['h1', 'h2', 'h2', 'h2']
60
['$49.90', '$7.50', '$12.00']
['A100', 'A200', 'A300']
['A100']
Sugar Water Feeder
['Ant Farm Deluxe', 'Sugar Water Feeder', 'Tunnel Kit & Extension']
['In stock', 'Out of stock', 'In stock']
['farm', 'glass']
3 3
['p', 'p']
soup.find('h9'): None
nav None
find returns the first match or None; find_all a list (empty when nothing matches). The filter can be a name, a list of names, True for any tag, a regex, or a function that receives the tag. Attributes go as keyword arguments (href=, id=), with class_ for the reserved word and an attrs dict for names that are not valid Python identifiers such as data-sku; True means "present". string= filters on text; limit= and recursive=False bound the search.
4. Select: CSS selectors via soupsieve
print(soup.select_one("#products h1").get_text(" ", strip=True))
print([p.string for p in soup.select("div.product p.price")])             # descendant
print([li.string for li in soup.select("div.featured > ul > li")])         # child
print([a["href"] for a in soup.select('a[href^="/p/"]')])                 # attribute prefix
print([a["href"] for a in soup.select('a[rel="nofollow"], a[href^="mailto:"]')])   # union
print(soup.select("div.product:nth-of-type(2) h2 a")[0].string)
print([d["data-sku"] for d in soup.select('div.product:has(p.stock.in)')])   # :has
print([p.string for p in soup.select('p:-soup-contains("Out")')])           # text match (soupsieve extension)
print(soup.select("table#orders tbody tr td:first-child")[0].string, len(soup.select("tbody tr")))
print(soup.select_one("h9"), soup.select("h9"))
# find_all and select say the same thing two ways
print(soup.find_all("p", class_="price") == soup.select("p.price"))
print(soup.find("div", attrs={"data-sku": "A300"}) == soup.select_one('div[data-sku="A300"]'))
Products (3)
['$49.90', '$7.50', '$12.00']
['farm', 'glass']
['/p/a100', '/p/a200', '/p/a300']
['https://example.com/help', 'mailto:hello@example.com']
Sugar Water Feeder
['A100', 'A300']
['Out of stock']
1001 3
None []
True
True
select takes any CSS selector soupsieve supports, including :has() and the soupsieve-only :-soup-contains(); select_one is the find equivalent. Use whichever reads better; the last two lines show they return the same elements. More selector forms are in BeautifulSoup CSS selectors.
5. Navigate
price = soup.find("p", class_="price")
print(price.parent.name, price.parent["data-sku"], [p.name for p in price.parents])
card = soup.find("div", class_="product")
print([type(c).__name__ for c in card.contents][:4])                    # whitespace strings are children too
print([c.name for c in card.children if c.name])                        # tags only
print(sum(1 for _ in card.descendants), len(card.find_all(True)))
print(repr(price.next_sibling))                                         # the newline, not the next tag
print(price.find_next_sibling().name, price.find_next_sibling("ul")["class"])
print(price.find_previous_sibling("h2").a.string)
print(price.find_parent("section")["id"], card.find_next_sibling("div")["data-sku"])
print(soup.find("th").next_element, soup.find("tbody").find_next("td").string)
div A100 ['div', 'section', 'body', 'html', '[document]']
['NavigableString', 'Tag', 'NavigableString', 'Tag']
['h2', 'p', 'p', 'ul']
17 7
'\n'
p ['tags']
Ant Farm Deluxe
products A200
Order 1001
The trap on this page is line five: .next_sibling of the price is the newline between tags, a NavigableString, not the next <p>. .contents and .children include those strings too (17 descendants but 7 tags). Use find_next_sibling(), find_previous_sibling(), find_parent() and find_next() when you mean the next tag; they take the same filters as find.
6. Text and attributes
h1 = soup.h1
print(repr(h1.string), "|", repr(h1.get_text()), "|", h1.get_text(" ", strip=True))   # .string is None with several children
print(soup.find("p", class_="price").string, soup.find("p", class_="price").text)
print(list(soup.find("div", class_="product").stripped_strings))
print(soup.nav.get_text("|", strip=True))
a = soup.find("a", class_="active")
print(a["href"], a.get("href"), a.get("target"), a.get("target", "_self"), a.has_attr("rel"))
show("a['target']", lambda: a["target"])
print(a["class"], soup.find("div", class_="featured")["class"])              # class is a list
print(soup.find("div", class_="featured").attrs)
print(soup.find("a", href="https://example.com/help")["rel"])              # rel is multi-valued too
None | 'Products (3)' | Products (3)
$49.90 $49.90
['Ant Farm Deluxe', '$49.90', 'In stock', 'farm', 'glass']
Home|Catalogue|Help
/catalogue /catalogue None _self False
a['target']: KeyError: 'target'
['active'] ['product', 'featured']
{'class': ['product', 'featured'], 'data-sku': 'A100'}
['nofollow']
.string is the text only when the tag has exactly one child string, otherwise None (the <h1> holds text plus a <small>); .get_text() concatenates everything below, and get_text(" ", strip=True) is the form you want for display. .text is an alias of .get_text(). stripped_strings iterates the pieces. For attributes, tag["x"] raises KeyError on a missing name, tag.get("x") returns None or your default; class and rel come back as lists because HTML defines them as multi-valued.
7. Modify
card = soup.find("div", attrs={"data-sku": "A200"})
card.find("p", class_="stock").string = "Back in stock"
card["class"].append("restocked"); card["data-updated"] = "2026-09-17"
new = soup.new_tag("p", attrs={"class": "note"}); new.string = "Ships in 2 days"
card.append(new)
card.insert(0, soup.new_tag("span", attrs={"class": "badge"}))
card.h2.insert_before(soup.new_string("[NEW] "))
print(card.prettify())
removed = soup.find("script").decompose()                     # gone, returns None
taken = soup.find("footer").extract()                          # removed and returned
print(removed, taken.name, soup.find("footer"))
soup.find("h1").small.unwrap()                                 # keep the text, drop the tag
soup.find("nav").wrap(soup.new_tag("header"))
print(soup.find("h1"), soup.find("header").nav["id"])
<div class="product restocked" data-sku="A200" data-updated="2026-09-17">
 <span class="badge">
 </span>
 [NEW]
 <h2>
  <a href="/p/a200">
   Sugar Water Feeder
  </a>
 </h2>
 <p class="price">
  $7.50
 </p>
 <p class="stock out">
  Back in stock
 </p>
 <ul class="tags">
  <li>
   feeder
  </li>
 </ul>
 <p class="note">
  Ships in 2 days
 </p>
</div>

None footer None
<h1>Products (3)</h1> top
decompose() destroys the element and returns None; extract() removes it and hands it back so you can reattach it elsewhere. unwrap() keeps the children and drops the tag, wrap() does the reverse, replace_with() swaps a node, clear() empties one. Note that changing the text did not change the stock out class; the tree does what you say, nothing more.
8. Output
h2 = soup.find("div", attrs={"data-sku": "A300"}).h2
print(str(h2))                                           # minimal formatter: & < > escaped
print(h2.decode(formatter="html"))                       # named entities
print(h2.decode(formatter=None))                         # no escaping at all
print(h2.encode("utf-8"))
print(h2.prettify(), end="")
<h2><a href="/p/a300">Tunnel Kit & Extension</a></h2>
<h2><a href="/p/a300">Tunnel Kit & Extension</a></h2>
<h2><a href="/p/a300">Tunnel Kit & Extension</a></h2>
b'<h2><a href="/p/a300">Tunnel Kit & Extension</a></h2>'
<h2>
<a href="/p/a300">
Tunnel Kit & Extension
</a>
</h2>
str() and decode() give a string, encode() bytes, prettify() the indented form (fine for reading, not for round-tripping whitespace-sensitive markup). The formatter argument decides how &, < and > in text come out: "minimal" (the default) escapes what must be escaped, "html" uses named entities where they exist, None writes the text raw.
One thing the 4.13 changelog describes that this version does not do for these builders: setting an attribute to True/False. The class that would do it, HTMLAttributeDict, exists in bs4/element.py, but none of the three HTML builders selects it by default; measured on 4.15.0 with html.parser, lxml and html5lib, a parsed or new tag's attributes are a plain AttributeDict, and the booleans are stringified:
soup.find("a", class_="active")["checked"] = True         # bool on a parsed tag
soup.find("a", href="/")["hidden"] = False
print(str(soup.nav), type(soup.nav.a.attrs).__name__)
box = soup.new_tag("input", attrs={"type": "checkbox"}); box["checked"] = True; box["disabled"] = False   # bool on a new tag
print(str(box), type(box.attrs).__name__)
<nav id="top">
<a hidden="False" href="/">Home</a>
<a checked="True" class="active" href="/catalogue">Catalogue</a>
<a href="https://example.com/help" rel="nofollow">Help</a>
</nav> AttributeDict
<input checked="True" disabled="False" type="checkbox"/> AttributeDict
So set boolean attributes as strings yourself (tag["checked"] = "" and del tag["hidden"]) rather than relying on that changelog entry.
9. Tables: rows, dicts, pandas
table = soup.find("table", id="orders")
rows = [[td.get_text(strip=True) for td in tr.find_all(["th", "td"])] for tr in table.find_all("tr")]
print(rows)
records = [dict(zip(rows[0], r)) for r in rows[1:]]
print(records[0])
df = pd.read_html(StringIO(str(table)))[0]
print(df.dtypes.to_dict()); print(df.to_string(index=False))
show("pd.read_html(str(table))  # the old spelling", lambda: len(pd.read_html(str(table))[0]))   # pandas 3 treats a str as a path
[['Order', 'SKU', 'Qty', 'Total'], ['1001', 'A100', '1', '$49.90'], ['1002', 'A200', '3', '$22.50'], ['1003', 'A300', '2', '$24.00']]
{'Order': '1001', 'SKU': 'A100', 'Qty': '1', 'Total': '$49.90'}
{'Order': dtype('int64'), 'SKU': <StringDtype(storage='python', na_value=nan)>, 'Qty': dtype('int64'), 'Total': <StringDtype(storage='python', na_value=nan)>}
 Order  SKU  Qty  Total
  1001 A100    1 $49.90
  1002 A200    3 $22.50
  1003 A300    2 $24.00
pd.read_html(str(table))  # the old spelling: FileNotFoundError: [Errno 2] No such file or directory: <table id="orders">
The list-of-lists is three lines and has no dependency; read_html gives you typed columns for free (Order and Qty became integers) and wants a file-like object: the 2024 version of this page passed a plain string, which pandas 3 treats as a path.
10. Deprecations: 4.13 to 4.15
4.13.0 (February 2025) added type hints to the whole library and turned the old camelCase names into DeprecationWarnings, with removal announced; 4.14.0 (September 2025) added overloads so that find/find_all results type-check without casts; 4.15.0 (June 2026) is the last release to support Python 3.7 and, per its changelog, the last to accept the deprecated names at all. With warnings enabled:
print(len(soup.findAll("p")))                          # camelCase: warns since 4.13, removal announced
print(soup.find("h1").getText(" ", strip=True))
print(repr(soup.find("th").nextSibling))
print([p.string for p in soup.find_all("p", text=re.compile("stock"))])   # text= -> string=
print([p.string for p in soup.find_all("p", string=re.compile("stock"))])
warning: DeprecationWarning: Call to deprecated method findAll. (Replaced by find_all) -- Deprecated since version 4.0.0.
7
Products (3)
warning: DeprecationWarning: Access to deprecated property nextSibling. (Replaced by next_sibling) -- Deprecated since version 4.0.0.
<th>SKU</th>
warning: DeprecationWarning: The 'text' argument to find()-type methods is deprecated. Use 'string' instead.
['In stock', 'Out of stock', 'In stock']
['In stock', 'Out of stock', 'In stock']
Python hides DeprecationWarning outside __main__ by default, so a library that still uses findAll is silent until it breaks; run your tests with -W default (or PYTHONWARNINGS=default) to see them; the package captured these with warnings.simplefilter("always"). Note that text= has warned since 4.11.0, and that getText is a plain alias of get_text and prints nothing. For typed code, the overloads added in 4.14 and reworked in 4.15 type find(name) as Tag | None and find(string=…) as NavigableString | None, so annotated assignments check without casts; the package runs this file through mypy:
from bs4 import BeautifulSoup, Tag, NavigableString

with open("fixtures/page.html", "rb") as f:
    soup = BeautifulSoup(f, "html.parser")
h2: Tag | None = soup.find("h2")                              # find(name) is typed Tag | None
first_stock: NavigableString | None = soup.find(string="In stock")   # find(string=...) is NavigableString | None
if h2 is not None:
    print(h2.name, h2.get_text())
if first_stock is not None:
    print(first_stock.parent.name if first_stock.parent else None)
prices: list[Tag] = list(soup.find_all("p", class_="price"))   # find_all(name) elements are Tag
print(len(prices))
h2 Ant Farm Deluxe
p
3
$ mypy 13_typing.py
Success: no issues found in 1 source file
huge_tree=True (4.14.3) passes through to lxml for pages with text nodes over 10 MB; the changelog notes it disables lxml's security restrictions, so use it on input you trust.
11. Errors you will meet
show("soup.find('p', class_='discount').text", lambda: soup.find("p", class_="discount").text)
tag = soup.find("p", class_="discount")
print(tag.text if tag else "no discount")
show("soup.select_one('p.discount').get_text()", lambda: soup.select_one("p.discount").get_text())
print(soup.select_one("p.discount").get_text() if soup.select_one("p.discount") else "no discount")
soup.find('p', class_='discount').text: AttributeError: 'NoneType' object has no attribute 'text'
no discount
soup.select_one('p.discount').get_text(): AttributeError: 'NoneType' object has no attribute 'get_text'
no discount
The most common BeautifulSoup error is not BeautifulSoup's: find returned None and the next attribute access fails. Guard it, or use find_all and iterate. The second most common is asking for a parser that is not installed; the package installs bs4 into a scratch directory without lxml and asks for it:
FeatureNotFound: Couldn't find a tree builder with the features you requested: lxml. Do you need to install a parser library?
x
pip install lxml, or name "html.parser", which is always there (the second line is that fallback working).
12. Which tool
| Need | Use |
|---|---|
| A tree you can walk, search and edit, from HTML that may be broken | BeautifulSoup with lxml (or html5lib for browser-identical parsing) |
| Speed on large pages, XPath, no editing | lxml.html directly (an order of magnitude faster in the table above) |
| XML with namespaces | lxml.etree or ElementTree, see How to parse XML in Python |
| A page's text for an LLM, or fields as JSON, without writing a parser | the ScrapingAnt Markdown and AI-extraction endpoints (below) |
When ScrapingAnt is not needed, and when it is
Parsing HTML you already have needs no service, and that is what this whole page is. The service enters on the fetch side, when the site blocks the client, or when the goal is not a tree at all. The Markdown endpoint, https://api.scrapingant.com/v2/markdown, accepts the same request structure as the general endpoint (url and x-api-key required) and returns a JSON object with url and markdown properties; it supports GET, POST, PUT and DELETE. The AI extractor, https://api.scrapingant.com/v2/extract, takes the general endpoint's parameters plus extract_properties, a free-form text describing the data to extract (for example: product title, price(number), full description); it returns a JSON object with camelCase property names and fills properties it cannot find with null. Cost: a request without a browser through a datacenter proxy costs 1 API credit, and AI extractor cost = ceil((markdown characters + output text characters) / 30) + the web-scraping request cost; each 30 characters of Markdown and output text cost 1 API credit, on top of the request cost (browser, proxy). Both endpoints are documented, not run here. See LLM-ready Markdown and the AI extractor.
How popular is BeautifulSoup in 2026
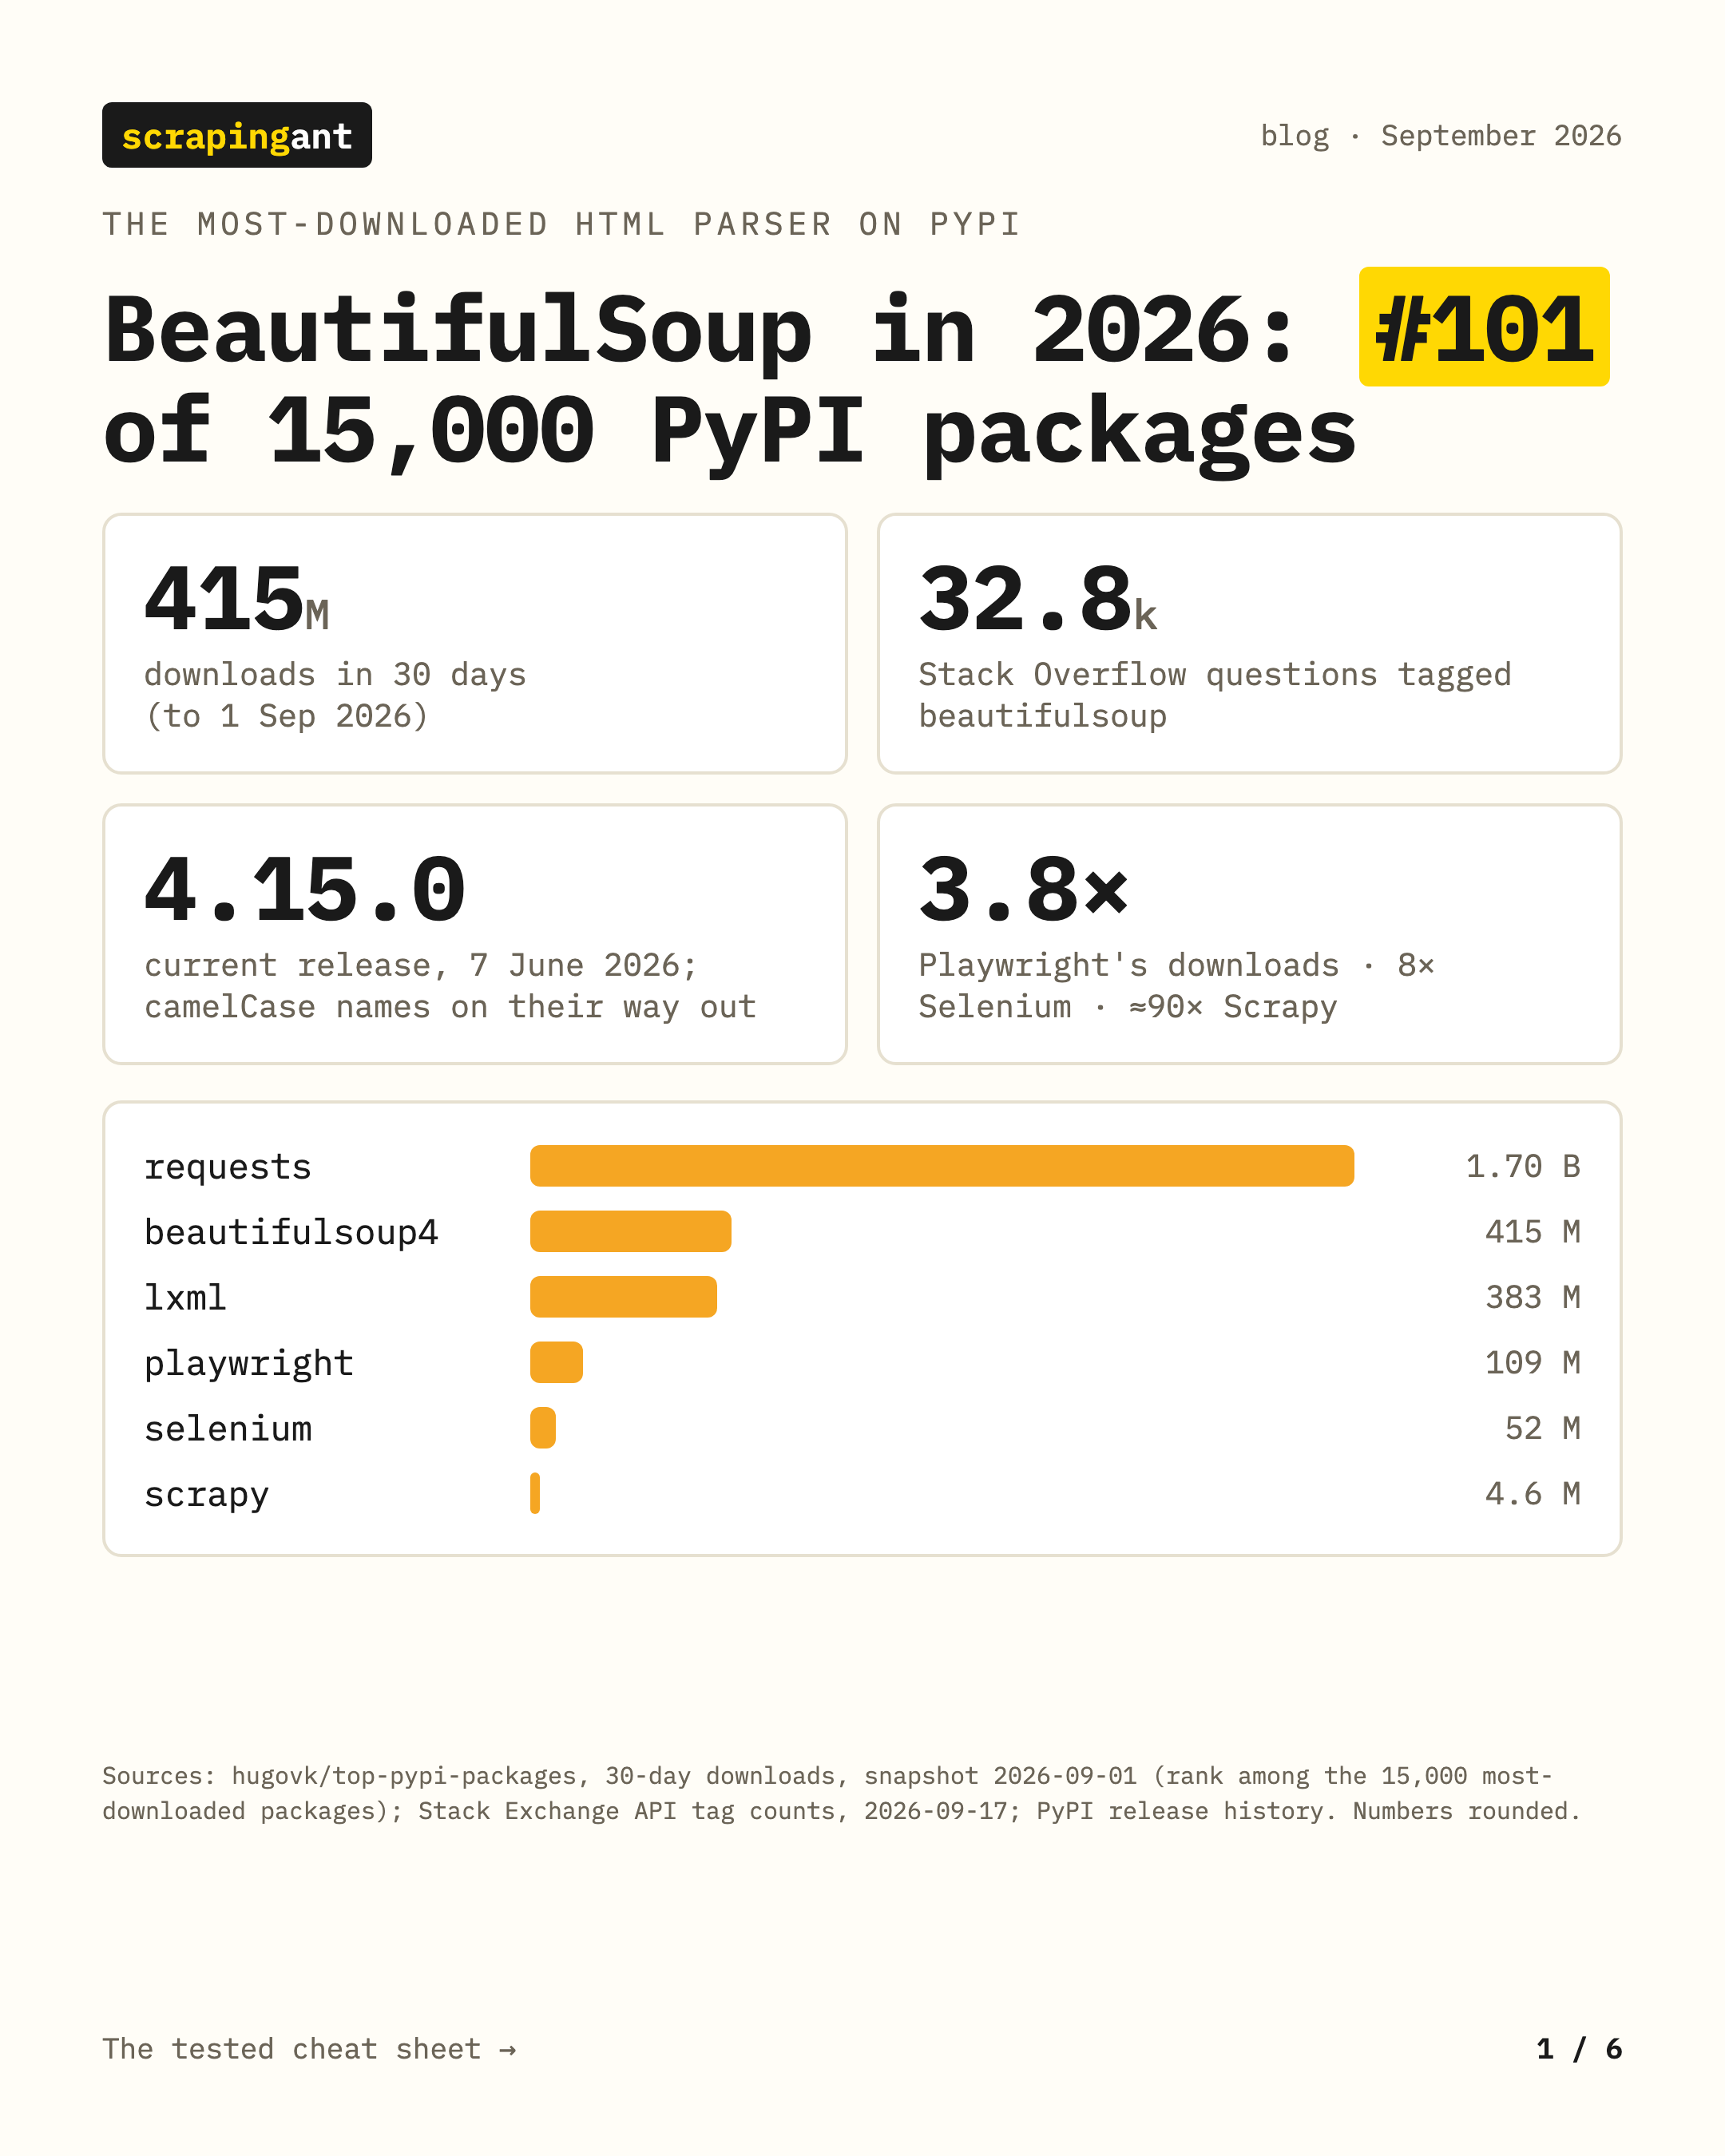
Two public counters, recorded by the package's popularity.py with their dates. In the 30-day download ranking of the 15,000 most-downloaded PyPI packages (snapshot 2026-09-01), beautifulsoup4 is number 101 with 414.8 million downloads; lxml is 109 (383.2M), playwright 308 (108.7M), selenium 533 (51.9M), scrapy 2,180 (4.6M, so about 90× fewer), and requests 7 (1.70B). On Stack Overflow (API, 2026-09-17) the beautifulsoup tag has 32,788 questions, against 99,924 for selenium, 17,825 for scrapy and 3,505 for playwright. Whatever the browser-automation tools do for JavaScript pages, the HTML they hand back still mostly goes through this library.
Limitations
- One fixture page and one broken fragment; the parser differences shown are the ones that fragment provokes.
- CPU time is from one machine and one page shape; the ratios in section 2 are from a quiet run, and earlier recordings under concurrent load moved them, so re-record before quoting a ranking of your own.
- The popularity numbers (and the infographic) are a dated snapshot from two public sources; re-run
popularity.pyfor today's. - The API endpoints are documented, not run.
Examples tested on 2026-09-17 with Python 3.12.11, beautifulsoup4 4.15.0, lxml 6.1.3 (libxml2 2.14.6), html5lib 1.1, soupsieve 2.9.2, pandas 3.0.5, mypy 1.19.1. Code: scrapingant-examples/examples/beautifulsoup-cheatsheet.
Related: BeautifulSoup CSS selectors, How to parse XML in Python, How to scrape a dynamic website with Python.
This article was drafted with AI assistance from a tested evidence packet and reviewed by the named author, who is responsible for the code, measurements and corrections.